12. File Systems
On a Unix-like system, a regular file is fundamentally a sequence of zero or more bytes. The filesystem gives that sequence a name, location and metadata, whilst the operating system provides controlled ways to open it and transfer bytes.
The file itself does not normally carry an authoritative declaration that it is “a JPEG”, “a C program” or “plain text”. A filename extension is a convention for humans and software. The meaning comes from the format in which a program interprets the bytes, just as the meaning of an integer bit pattern depends on its type in Integers.
From a Pathname to Bytes#
A persistent storage device contains blocks, not an inherent tree of familiar filenames. A filesystem maintains the structures which map pathnames to file data and metadata.
flowchart LR
    P["pathname<br/>notes/week5.md"] --> FS["filesystem lookup"]
    FS --> M["metadata<br/>type, size, permissions"]
    FS --> B["storage locations<br/>containing file bytes"]
    B --> RAM["bytes copied into RAM<br/>when read"]
The precise on-disk structures vary between filesystems, but programs do not ordinarily need to know them. They ask the kernel to resolve a pathname, and the kernel communicates with the filesystem and device driver.
A Unix file is a byte stream#
For a regular file, the OS exposes an ordered sequence of bytes and a size. Structure beyond that is imposed by the program:
- a text editor interprets some byte sequences as encoded characters;
- an image viewer interprets headers, dimensions and compressed pixel data;
- the loader interprets an executable format as code and data segments;
- a compiler interprets bytes as source-language tokens.
This is why opening a binary file in a text editor produces nonsense: the text editor is applying the wrong interpretation, not discovering that the file has “become corrupted”.
File Descriptors#
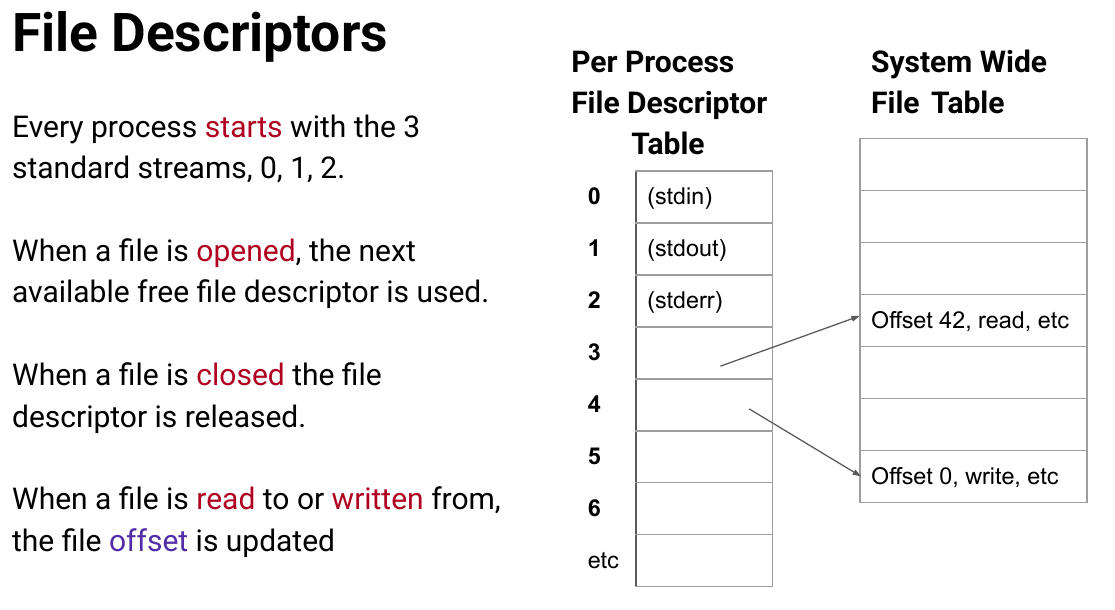
Before using read or write, a process normally obtains a file descriptor. A file descriptor is a small, non-negative integer used by that process to refer to a kernel-managed I/O object such as a regular file, pipe, terminal, device or socket.
There are three separate objects in this story:
- The file is the persistent object and its bytes on the filesystem.
- An open file description is a temporary kernel record created when a file is opened. It remembers how this particular opening is being used, including the current offset and status flags.
- A file descriptor is the small number a process uses to reach that kernel record.
The descriptor is best understood as an index into a per-process table maintained by the kernel. It is similar to a claim-ticket number: the number is not the file, and another process can reuse the same number for something completely different. Following the table entry leads to the open file description, which then leads to the underlying file or pipe endpoint.
The diagrams use inode numbers to identify the underlying filesystem objects. An inode is the filesystem record which identifies an object and stores its metadata; File System Metadata and Directories develops that layer fully.
Process A: descriptor 3
| Descriptor-table entry | Open-file description | File object |
|---|---|---|
fd 3 |
log.txt, offset 128, write-only |
inode 1042 |
Process B: descriptor 3
| Descriptor-table entry | Open-file description | File object |
|---|---|---|
fd 3 |
data.bin, offset 512, read-only |
inode 3891 |
Descriptors are local to a process. File descriptor 3 in Process A refers to log.txt, whereas descriptor 3 in Process B refers to data.bin.
Two processes can also open the same file independently. Their descriptors lead to separate open file descriptions—and therefore separate offsets—even though both descriptions eventually refer to the same inode:
| Process entry | Its open-file description | Underlying file |
|---|---|---|
Process A, fd 4 |
offset 0, read-only | data.bin, inode 3891 |
Process B, fd 3 |
offset 512, read-only | data.bin, inode 3891 |
The two calls opened the same file object but created independent open-file descriptions, so advancing A's offset does not advance B's.
The Linux open documentation describes the returned descriptor as the lowest currently unused non-negative integer and distinguishes the per-process descriptor from its system-wide open file description: open(2).
The current file offset#
For a seekable file, the open file description records a byte offset. A successful read or write normally begins there and advances it by the number of bytes transferred.
file bytes:   H e l l o ,   w o r l d !
offset:       0 1 2 3 4 5 6 7 8 9 ...
                           ^
                    current offset 6
After reading five bytes from offset 0, the next read begins at offset 5 unless the program changes the offset with lseek or another operation.
Standard Streams#
Every ordinary Unix process begins with three conventional descriptors:
| Descriptor | Name | C macro | Default connection |
|---|---|---|---|
| 0 | standard input | STDIN_FILENO |
terminal keyboard input |
| 1 | standard output | STDOUT_FILENO |
terminal display |
| 2 | standard error | STDERR_FILENO |
terminal display |
They are treated through the same descriptor interface as opened files, pipes and many devices. A program which reads descriptor 0 does not need to know whether the bytes come from a keyboard, a file or another process.
Why standard error exists#
Separating ordinary output from diagnostics allows a user to redirect them independently:
./program >output.txt
./program 2>errors.txt
./program >output.txt 2>errors.txt
This matters for programs whose standard output is intended for another program. An error message mixed into a data stream could corrupt it.
In C, the corresponding <stdio.h> streams are stdin, stdout and stderr:
fprintf(stdout, "result: %d\n", result);
fprintf(stderr, "invalid input\n");
Note
Checkpoint
- A pathname is resolved by the filesystem; an open file descriptor is the process's handle to the result.
- Descriptor numbers are process-local indexes, while the underlying open file description holds shared state such as the offset.
- Descriptors
0,1, and2are ordinary handles with conventional roles: standard input, output, and error.
The File I/O Lifecycle#
Low-level file I/O generally follows four stages:
The normal lifecycle is: call open() to obtain a descriptor, use that descriptor in read() or write() zero or more times, then call close() when this process no longer needs it.
Each call can fail, so a correct program checks every return value rather than assuming that a valid-looking request succeeded.
Opening a File#
The open wrapper is declared in <fcntl.h>:
#include <fcntl.h>

int open(const char *path, int flags, ...);
On success it returns a file descriptor. On failure it returns -1 and sets errno.
Exactly one access mode is required:
| Flag | Meaning |
|---|---|
O_RDONLY |
open for reading only |
O_WRONLY |
open for writing only |
O_RDWR |
open for both reading and writing |
Additional flags change how the open occurs:
| Flag | Effect |
|---|---|
O_APPEND |
move to the end as part of each write operation |
O_CREAT |
create the file if it does not exist |
O_EXCL |
with O_CREAT, fail if the file already exists |
O_TRUNC |
reduce an existing regular file to length zero |
Flags are combined with bitwise OR, as described in Bitwise Operations:
int fd = open("output.txt", O_WRONLY | O_CREAT | O_TRUNC, 0644);The third mode argument is required when O_CREAT may create a file. It supplies permission bits, which are modified by the process's umask.
Permissions and octal#
Unix permissions are naturally written in octal because each octal digit represents the three read, write and execute bits for one permission class. Thus 0644 grants read and write to the owner and read-only access to the group and others. The leading 0 is C's octal prefix; decimal 644 would set an entirely different bit pattern. Octal Permissions develops the full mapping.
Opening safely#
#include <fcntl.h>
#include <stdio.h>
#include <stdlib.h>

int fd = open("input.txt", O_RDONLY);
if (fd == -1) {
    perror("input.txt");
    exit(EXIT_FAILURE);
}
perror uses the current errno value to append a human-readable reason.
Common I/O Types#
The function signatures deliberately use types suited to byte counts and file offsets:
| Type | Signed? | Purpose |
|---|---|---|
size_t |
unsigned | size or count of bytes in memory |
ssize_t |
signed | byte count or -1 error indication |
off_t |
signed | file size or offset |
read cannot return a size_t, because an unsigned type has no ordinary -1 error value. ssize_t can represent both non-negative byte counts and failure.
Avoid storing a read result directly in size_t:
size_t n = read(fd, buffer, sizeof buffer); // dangerousIf read returns -1, converting it to unsigned produces a very large number. Use ssize_t and test for -1 before any conversion.
Reading Bytes#
The read wrapper is declared in <unistd.h>:
#include <unistd.h>

ssize_t read(int fd, void *buffer, size_t count);
It attempts to place up to count bytes into the memory beginning at buffer.
Its return value has three distinct meanings:
| Return | Meaning |
|---|---|
| positive | number of bytes actually read |
0 |
when count > 0, end of input: a regular file is at EOF, or a pipe has no remaining writers |
-1 |
error; errno describes the cause |
The word “up to” is essential. A successful read may return fewer bytes than requested. This is common for pipes, terminals and network connections, and can also occur when a regular file ends. The Linux read(2) documentation specifies that the file offset advances by the number of bytes actually read for seekable files.
There is one boundary case: read(fd, buffer, 0) is permitted to return 0 without testing whether useful input remains. A zero return is therefore evidence of end-of-input only when the program actually requested a positive number of bytes. Ordinary read loops naturally satisfy this by passing the non-zero size of their buffer.
char buffer[4096];
ssize_t bytes_read = read(fd, buffer, sizeof buffer);

if (bytes_read == -1) {
    perror("read");
} else if (bytes_read == 0) {
    // end-of-file
} else {
    // exactly bytes_read bytes in buffer are valid
}
read does not append a null terminator. The result is a sequence of bytes, not automatically a C string. If text is intended, reserve an extra byte and terminate it yourself:
char buffer[4097];
ssize_t n = read(fd, buffer, 4096);
if (n > 0) {
    buffer[n] = '\0';
}
Practice: Quick Checks#
- Distinguish a pathname, a file descriptor and an open file description. Which of the three contains the current file offset?
- What do
read()returns of-1,0, and a positive value mean? Why isssize_tsuitable for this interface?
Note
- Quick Check Answers
- A pathname names an object during lookup; a descriptor is a process-local integer handle; an open file description is kernel state for an open instance. The open file description contains the offset.
-1reports an error, a positive value is the number of bytes transferred, and0reports end of input when a positive count was requested. A zero-byte request can also return0without establishing EOF. A signed type can represent both non-negative counts and-1.
Writing Bytes#
The write wrapper is also declared in <unistd.h>:
ssize_t write(int fd, const void *buffer, size_t count);It attempts to transfer count bytes beginning at buffer to the I/O object reached through fd.
| Return | Meaning |
|---|---|
| non-negative | number of bytes actually written |
-1 |
error; errno describes the cause |
A successful write may write fewer bytes than requested. Code which must emit the complete buffer needs a loop:
#include <errno.h>
#include <unistd.h>

ssize_t write_all(int fd, const void *buffer, size_t count) {
    const unsigned char *bytes = buffer;
    size_t written = 0;

    while (written < count) {
        ssize_t result = write(fd, bytes + written, count - written);

        if (result == -1) {
            if (errno == EINTR) {
                continue;
            }
            return -1;
        }

        // No progress with bytes still pending would otherwise loop forever.
        if (result == 0) {
            errno = EIO;
            return -1;
        }

        written += (size_t)result;
    }

    return (ssize_t)written;
}
This loop advances the pointer by the number of bytes already written and requests only the remaining count.
Seeking with lseek#
Sequential I/O moves the current offset forward by the number of bytes read or written. Seeking explicitly changes this file offset without transferring data.
The lseek system call is declared in <unistd.h>:
#include <unistd.h>

off_t lseek(int fd, off_t offset, int whence);
The whence parameter specifies how offset is interpreted:
whence Constant |
Meaning | New File Offset |
|---|---|---|
SEEK_SET |
Relative to the start of the file | offset |
SEEK_CUR |
Relative to the current file offset | current_offset + offset |
SEEK_END |
Relative to the end of the file | file_size + offset |
On success, lseek returns the resulting file offset (in bytes from the beginning of the file). On failure, it returns (off_t)-1 and sets errno.
// Determine the total size of a file
off_t file_size = lseek(fd, 0, SEEK_END);
if (file_size == (off_t)-1) {
    perror("lseek");
}

// Rewind back to the beginning
if (lseek(fd, 0, SEEK_SET) == (off_t)-1) {
    perror("lseek");
}
Seeking past the end and sparse files#
POSIX allows seeking past the current end of a regular file. A read at that position returns 0 because the offset is beyond EOF. If data is later written there, the intervening gap reads back as zero bytes. Filesystems which represent that gap without allocating physical data blocks create a sparse file, or a file with a hole; POSIX specifies the observable zero bytes, not whether the storage is physically sparse.
Note
lseek only works on seekable files (such as regular disk files). Attempting to seek on a terminal, pipe, or socket returns -1 with errno set to ESPIPE.
Note
Checkpoint
read()andwrite()may transfer fewer bytes than requested, so robust code loops over the remainder.read() == 0means EOF for a regular file and means that a pipe has no writers left once buffered data is exhausted.lseek()changes the current offset without transferring bytes and works only on seekable objects.
Practice: Tracing and Calculation#
- A file offset begins at 10.
read(fd, buf, 8)returns 3, thenlseek(fd, -2, SEEK_CUR)succeeds. What is the final offset? write(fd, data, 100)returns 37. Did it fail, and what arguments should the next call use ifdatais a byte pointer?
Note
- Tracing and Calculation Answers
3. The read advances the offset to 13; seeking back two bytes leaves it at 11.
4. It succeeded partially. The next call should start at data + 37 and request the remaining 63 bytes, while still handling interruption, failure and another short write.
Closing a Descriptor#
int close(int fd);close releases the process's descriptor so the number can be reused. It returns 0 on success or -1 on error.
if (close(fd) == -1) {
    perror("close");
}
Closing is important because a process can have only a limited number of descriptors open. The kernel also needs to release its references and related state.
Do not continue using a descriptor after closing it. The same integer may soon be returned by another open and refer to a completely different object.
Error Reporting with errno#
Many libc system-call wrappers use the convention:
- return a value such as
-1to indicate failure; - set
errnoto an error code describing the reason.
#include <errno.h>
#include <stdio.h>
#include <string.h>

if (fd == -1) {
    fprintf(stderr, "open failed: %s\n", strerror(errno));
}
perror is a convenient alternative:
if (fd == -1) {
    perror("open");
}
The value of errno is meaningful only after a function reports an error. A successful function call is not required to clear it, so this is wrong:
read(fd, buffer, size);
if (errno != 0) {     // wrong: errno may be left over from an earlier call
    // ...
}
Always inspect the function's documented return value first. The Linux manual's errno(3) page makes this rule explicit.
Common errors include:
| Name | Typical meaning |
|---|---|
ENOENT |
a pathname component does not exist |
EACCES |
permission denied |
EBADF |
invalid descriptor, or wrong access mode |
EINTR |
operation interrupted by a signal |
ENOSPC |
no space remains on the device |
Do not memorise this table as exhaustive. Use man 2 open, man 2 read or the relevant manual page for the call being made.
Practice: Writing and Debugging#
- Write the
open()flags and mode for “create a new output file for owner read/write and group read; fail if it already exists”. Why is the leading zero important? - A program does
read(fd, buffer, 32); if (errno != 0) .... Explain the bug and give the correct decision order.
Note
- Writing and Debugging Answers
5. open(path, O_WRONLY | O_CREAT | O_EXCL, 0640). The leading zero makes 0640 an octal C literal, matching three-bit permission groups. This is the requested creation mode; the process's umask can remove permissions, so the resulting mode is 0640 & ~umask.
6. A successful call may leave an old non-zero errno. Store and inspect the return value first; only interpret errno if that value reports failure.
Worked Example: Copying a File#
This example combines open, read, repeated write and close:
#include <errno.h>
#include <fcntl.h>
#include <stdio.h>
#include <stdlib.h>
#include <unistd.h>

int main(int argc, char **argv) {
    if (argc != 3) {
        fprintf(stderr, "usage: %s <source> <destination>\n", argv[0]);
        return EXIT_FAILURE;
    }

    int input_fd = open(argv[1], O_RDONLY);
    if (input_fd == -1) {
        perror(argv[1]);
        return EXIT_FAILURE;
    }

    int output_fd = open(
        argv[2],
        O_WRONLY | O_CREAT | O_TRUNC,
        0644
    );
    if (output_fd == -1) {
        perror(argv[2]);
        close(input_fd);
        return EXIT_FAILURE;
    }

    unsigned char buffer[4096];
    int failed = 0;

    while (!failed) {
        ssize_t n_read = read(input_fd, buffer, sizeof buffer);

        if (n_read == 0) {
            break;
        }
        if (n_read == -1) {
            if (errno == EINTR) {
                continue;
            }
            perror("read");
            failed = 1;
            break;
        }

        ssize_t offset = 0;
        while (offset < n_read) {
            ssize_t n_written = write(
                output_fd,
                buffer + offset,
                (size_t)(n_read - offset)
            );

            if (n_written == -1) {
                if (errno == EINTR) {
                    continue;
                }
                perror("write");
                failed = 1;
                break;
            }

            if (n_written == 0) {
                fprintf(stderr, "write made no progress\n");
                failed = 1;
                break;
            }

            offset += n_written;
        }
    }

    if (close(input_fd) == -1) {
        perror("close input");
        failed = 1;
    }
    if (close(output_fd) == -1) {
        perror("close output");
        failed = 1;
    }

    return failed ? EXIT_FAILURE : EXIT_SUCCESS;
}
The important mechanics are:
readcontinues until it returns 0;- the buffer is treated as bytes, so it can copy text or binary data;
- partial writes are handled by an inner loop;
EINTRretries the interrupted operation;- each opened descriptor is eventually closed;
- every operation's return value is checked.
Warning
- Source and destination must be different files
If both pathnames resolve to the same underlying file, opening the destination with O_TRUNC empties it before the first read. A production-quality copy tool checks file identity before truncating; for course exercises, at least test that you did not supply the same pathname twice.
File Descriptors Versus FILE *#
Low-level POSIX I/O uses integer descriptors, while the C standard I/O library uses buffered FILE * streams. A stream on a Unix-like system normally refers to an underlying descriptor but also maintains its own buffer, positioning and status information. Files and Streams gives the complete comparison and explains how to coordinate the two interfaces safely.
Practice: Challenge#
- Why can opening a destination with
O_TRUNCdestroy the source before a copy starts even when the two pathname strings differ? - A program writes diagnostics to descriptor 1 and data to descriptor 2. What practical problem appears when a shell user redirects or pipes the program?
Note
- Challenge Answers
7. Different pathnames can be hard links or otherwise resolve to the same underlying file. Truncating through either name changes that shared object before the input is read.
8. The conventional streams are reversed: the pipeline receives diagnostics as data, while the intended data follows the error channel. Ordinary output belongs on descriptor 1 and diagnostics on descriptor 2.
These operations are concrete examples of the controlled service boundary introduced in Operating Systems. Files and Streams continues from these low-level descriptor operations into buffered standard I/O.