11. Concurrency and Threads
Concurrency means multiple computations make progress during overlapping periods of time. They do not need to execute at the same instant. Parallelism means multiple computations literally execute simultaneously, which normally requires multiple CPU cores or other processing units.
flowchart TB
    C["Concurrency on one core<br/>A → B → A → B"]
    P["Parallelism on two cores<br/>Core 1: A | Core 2: B"]
    C ~~~ P
A concurrent program may become parallel when the OS schedules its work across cores, but concurrency is primarily about program structure and overlapping progress.
Flynn's Taxonomy#
Flynn's taxonomy classifies computation by the number of instruction and data streams:
| Class | Meaning | Course-scale example |
|---|---|---|
| SISD | single instruction, single data | ordinary sequential MIPS in mipsy |
| SIMD | single instruction, multiple data | vector instructions or GPU-style data parallelism |
| MISD | multiple instruction, single data | uncommon; sometimes used to describe replicated fault-tolerant processing |
| MIMD | multiple instruction, multiple data | independent threads or processes across CPU cores |
This is a vocabulary for kinds of parallel hardware and computation. It is separate from the concurrency/parallelism distinction: a program can be concurrent while taking turns on one SISD core.
Processes or Threads?#
Processes can run concurrently and provide strong isolation, but each process has its own address space. Communicating through Pipes and File Redirection or another inter-process communication (IPC) mechanism therefore requires explicit work.
Threads provide concurrency within one process. Threads in the same process share:
- program code;
- global and static variables;
- heap allocations;
- open file descriptors;
- environment variables and current working directory.
Each thread has its own:
- registers and program counter;
- stack;
- thread ID;
- thread-local state such as
errno.
flowchart TB
    subgraph Process["One process"]
        SHARED["Shared by every thread<br/>code · globals · heap<br/>file descriptors · environment · CWD"]
        T1["Thread 1<br/>registers + PC · stack<br/>TID · thread-local state"]
        T2["Thread 2<br/>registers + PC · stack<br/>TID · thread-local state"]
        T3["Thread 3<br/>registers + PC · stack<br/>TID · thread-local state"]

        SHARED --- T1
        SHARED --- T2
        SHARED --- T3
    end
Although each thread has its own stack, the stacks occupy the shared address space. One thread can technically access another thread's stack through a pointer. The problem is not access permission; it is ensuring that the pointed-to object still exists.
Creating a POSIX Thread#
POSIX threads, or pthreads, are declared in <pthread.h>. Compilation commonly needs -pthread:
dcc -pthread program.c -o programA thread starts in a function with this exact shape:
void *worker(void *argument);pthread_create() launches it:
int pthread_create(
	pthread_t *thread,
	const pthread_attr_t *attributes,
	void *(*start_routine)(void *),
	void *argument
);#include <pthread.h>
#include <stdio.h>
#include <stdlib.h>
void *worker(void *argument) {
char *name = argument;
printf("hello from %s\n", name);
return NULL;
}
int main(void) {
pthread_t thread;
int error = pthread_create(&thread, NULL, worker, "the worker");
if (error != 0) {
fprintf(stderr, "pthread_create failed: %d\n", error);
return 1;
}
error = pthread_join(thread, NULL);
if (error != 0) {
fprintf(stderr, "pthread_join failed: %d\n", error);
return 1;
}
return 0;
}Like posix_spawn(), pthread functions usually return an error number directly rather than setting errno.
Joining Threads#
int pthread_join(pthread_t thread, void **result);Joining waits until the chosen thread finishes and optionally collects its return pointer. If main() returns, the process terminates and all other threads disappear, whether or not they finished. A process must therefore join threads whose work it needs.
A worker can finish by returning from its start routine or by calling pthread_exit(result). Returning is usually clearer. The result pointer follows the same lifetime rules either way.
void *worker(void *unused) {
	long *answer = malloc(sizeof *answer);
	if (answer == NULL) {
		return NULL;
	}
	*answer = 42;
	return answer;
}

// Later in main:
void *result;
int error = pthread_join(thread, &result);
if (error != 0) {
	fprintf(stderr, "pthread_join failed: %d\n", error);
	return 1;
}

long *answer = result;
if (answer != NULL) {
	printf("%ld\n", *answer);
	free(answer);
}
Never return a pointer to a worker's local variable. Its stack frame ceases to exist when the thread returns.
Passing Data Safely#
pthread_create() passes one void *, so a structure is useful for multiple values:
struct task {
	const int *values;
	size_t start;
	size_t end;
	long result;
};

void *sum_range(void *raw) {
	struct task *task = raw;
	task->result = 0;
	for (size_t i = task->start; i < task->end; i++) {
		task->result += task->values[i];
	}
	return NULL;
}
The pointed-to task must remain alive until the worker has finished. Safe choices include:
- storage in
main()whenmain()joins all workers before returning; - a heap allocation freed after the join;
- static storage, when sharing that lifetime and access pattern is intentional.
A classic bug passes the address of one loop variable to every worker:
for (int i = 0; i < THREADS; i++) {
	pthread_create(&threads[i], NULL, worker, &i); // broken
}
All workers receive the same address. By the time they read it, the loop may have changed i or ended. Store one stable argument object per thread.
struct task tasks[THREADS];

for (size_t i = 0; i < THREADS; i++) {
	tasks[i].values = values;
	tasks[i].start = starts[i];
	tasks[i].end = ends[i];
	pthread_create(&threads[i], NULL, sum_range, &tasks[i]);
}

// Keep tasks alive and unchanged until the corresponding joins complete.
Worked trace: splitting and recombining work#
Suppose values is {4, 7, 1, 8, 3, 2} and two workers should sum disjoint halves. main prepares both task objects before creating the workers:
| Task | Half-open range | Values included | Partial sum |
|---|---|---|---|
| 0 | [0, 3) |
values[0] + values[1] + values[2] |
12 |
| 1 | [3, 6) |
values[3] + values[4] + values[5] |
13 |
struct task tasks[2] = {
	{.values = values, .start = 0, .end = 3},
	{.values = values, .start = 3, .end = 6},
};
pthread_t threads[2];

for (size_t i = 0; i < 2; i++) {
	int error = pthread_create(&threads[i], NULL, sum_range, &tasks[i]);
	if (error != 0) {
		// Production code must decide how to join any workers already created.
		fprintf(stderr, "pthread_create failed: %d\n", error);
		exit(1);
	}
}

for (size_t i = 0; i < 2; i++) {
	int error = pthread_join(threads[i], NULL);
	if (error != 0) {
		fprintf(stderr, "pthread_join failed: %d\n", error);
		exit(1);
	}
}

long total = tasks[0].result + tasks[1].result;  // 25
Each worker writes a different result field, so those writes do not race with one another. main reads the fields only after both joins. The joins provide the required ordering: each worker has finished its write before main combines the results.
Note
Checkpoint
- Threads share globals, heap objects, and descriptors, but each thread has its own registers and stack.
- The argument passed to a worker must remain alive and stable until that worker has finished using it.
pthread_join()both waits for completion and lets the caller collect the worker's result.
When Threads Help#
Threads can improve a program when:
- independent CPU-heavy work can run on several cores;
- one thread can make progress while another blocks on I/O;
- a user interface must remain responsive during background work;
- shared-memory communication is cheaper than process IPC.
They do not automatically make code faster. Thread creation, scheduling, cache traffic and synchronisation all have costs. If the task is tiny, sequential code can be quicker. A calculation with unavoidable sequential dependencies cannot be divided arbitrarily.
Data Races#
A data race occurs when threads access the same memory concurrently, at least one access writes it, and the accesses are not properly synchronised.
Here, concurrently does not require two CPU cores to touch the value at precisely the same instant. It is enough that the operations can overlap in time or be interleaved without an ordering rule. An expression such as counter++ is not one indivisible action: it normally reads the old value, calculates a new one, then writes it back.
int bank_account = 0;

void *deposit(void *unused) {
	bank_account++;
	return NULL;
}
bank_account++ looks like one C expression, but at machine level it is a read-modify-write sequence:
load bank_account
add 1
store bank_account
Two threads can both load 42, both calculate 43, and both store 43. One increment is lost.
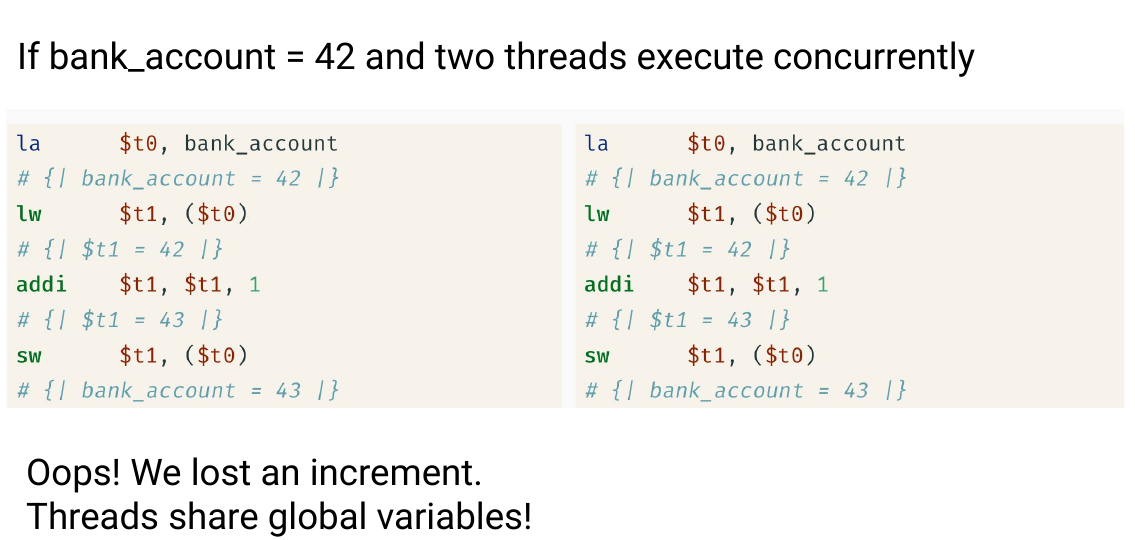
In C, a data race is undefined behaviour. This means the C language stops promising what the program will do; it does not mean the language promises one random-but-reasonable answer. A compiler may assume correctly synchronised code is race-free and optimise on that basis, while the CPU and caches may expose memory operations in surprising orders. The program might appear to work in one build and fail after an unrelated edit or optimisation change.
Practice: Quick Checks#
- Name three resources shared by threads in one process and three pieces of per-thread state.
- State the conditions for a C data race. Does alternating threads on one CPU core make an unsynchronised shared write safe?
Note
- Quick Check Answers
- Code, globals/heap objects and open descriptors are shared. Registers/program counter, stack and thread ID are per-thread.
- Different threads access the same memory location, at least one access writes, at least one access is non-atomic, and no synchronisation operation guarantees that one access finishes before the other begins. One core does not make this safe: the scheduler can still interleave the operations.
Critical Sections and Mutexes#
A critical section accesses shared state which must not be manipulated by multiple threads at once. A mutex establishes mutual exclusion: only the thread which successfully locks it enters the protected region; another thread trying to lock it waits.
int bank_account = 0;
pthread_mutex_t bank_lock = PTHREAD_MUTEX_INITIALIZER;

void *deposit_many(void *unused) {
	for (int i = 0; i < 100000; i++) {
		pthread_mutex_lock(&bank_lock);
		bank_account++;
		pthread_mutex_unlock(&bank_lock);
	}
	return NULL;
}
The mutex protects a rule about data, not just a line of code. Such a rule is called an invariant: something which must be true whenever other code is allowed to observe the state. If an account's balance and transaction number must describe the same update, both fields belong to one invariant. Every read and write participating in that rule must use the same mutex. Locking only the writers while readers access the variables unsynchronised is still broken.
Keep critical sections as small as correctness permits, but not smaller. If two fields must change together to preserve an invariant, protect the whole multi-step update.
Warning
- Always unlock on every path
A return, break or error path inside a critical section can leave the mutex permanently locked. Structure the function so cleanup is unavoidable and easy to verify.
Deadlock#
A deadlock occurs when threads wait forever for one another. Consider two locks:
Thread 1 acquires A and then asks for B, while Thread 2 acquires B and then asks for A. Each thread is holding the resource the other needs, producing the cycle shown below.
If Thread 1 owns A while Thread 2 owns B, each waits for a lock which the other cannot release.
flowchart TB
    T1["Thread 1<br/>holds Lock A"] -->|"waits for"| LB["Lock B"]
    LB -->|"held by"| T2["Thread 2<br/>holds Lock B"]
    T2 -->|"waits for"| LA["Lock A"]
    LA -->|"held by"| T1
A powerful prevention rule is to enforce a strict global lock acquisition hierarchy. If every thread acquires Lock A before Lock B, circular waiting cannot occur. Releasing locks in reverse order of acquisition is standard practice.
Note
Checkpoint
- A data race is undefined behaviour, not merely an unlucky final value.
- A mutex protects an invariant by making the entire critical section mutually exclusive.
- Consistent lock ordering prevents the circular wait that causes deadlock.
Practice: Tracing and Calculation#
counterbegins at 20. Thread A and Thread B each execute a non-atomic load, increment and store once. Give an interleaving which leavescounter == 21rather than 22.- Thread A locks
leftthen waits forright; Thread B locksrightthen waits forleft. Draw the wait cycle and state one design rule which prevents it.
Note
- Tracing and Calculation Answers
3. A loads 20; B loads 20; A calculates and stores 21; B calculates and stores 21. One update is lost.
4. A waits for right, held by B; B waits for left, held by A. Require every thread to acquire the locks in one global order, such as left before right.
Atomics#
For simple shared values, C atomic types can make individual operations indivisible:
#include <stdatomic.h>

atomic_int bank_account = 0;

void *deposit_many(void *unused) {
	for (int i = 0; i < 100000; i++) {
		bank_account += 1;
	}
	return NULL;
}
Atomic compound operations such as ++, +=, -=, |=, &= and ^= perform an atomic read-modify-write on an atomic object. Explicit functions are also available:
int old_value = atomic_fetch_add(&bank_account, 1);However:
bank_account = bank_account + 1;is an atomic load followed by a separate atomic store. Another thread can intervene between them, so the whole increment is not atomic.
Atomics are not a universal mutex replacement. If correctness depends on a relationship between several variables or several operations, one atomic operation may not protect the invariant. Memory ordering also becomes subtle beyond COMP1521's scope.
Practice: Writing and Debugging#
- Why is passing
&ifrom one loop variable to everypthread_create()call unsafe? Describe a correct storage arrangement. atomic_int x = 0;is shared. Comparex += 1;withx = x + 1;. Which is one atomic read-modify-write operation?
Note
- Writing and Debugging Answers
5. Every worker receives the same address and may observe a later value or an expired object. Store one stable argument per thread—for example, an array of task structures kept alive until all joins complete.
6. x += 1 is an atomic read-modify-write on an atomic object. x = x + 1 performs a separate atomic load and store, allowing another thread to intervene.
Mutex or Atomic?#
| Situation | Usually appropriate |
|---|---|
| one counter increment | atomic operation |
| several fields must change together | mutex |
| complex conditional update | mutex, unless carefully designed otherwise |
| blocking I/O while holding protection | reconsider the design; avoid a long-held mutex |
A mutex is easier to reason about for compound state. Atomics can be cheaper and cannot themselves form a lock-order deadlock, but lock-free does not mean mistake-free.
Practice: Challenge#
- A structure contains
balanceandlast_transaction_id, which must describe the same transaction. Why are two independent atomic stores insufficient to preserve that invariant for readers? - A worker returns
&local_result, andmain()prints it afterpthread_join(). Why does joining not make the pointer valid? Give one valid alternative.
Note
- Challenge Answers
7. A reader can observe one new field and one old field between the stores. Protect the compound update and matching reads with one mutex, or design a genuinely atomic combined representation.
8. The worker's stack frame ceased to exist when it returned; joining waits but does not restore that storage. Return heap-allocated storage which the joiner frees, or write into caller-owned storage which remains alive through the join.
Note
- Further reading
The course's official Threads topic notes contain the full progression from pthread_create() to atomics. The exact contracts are in POSIX; in the CSE environment, start with man 3 pthread_create, man 3 pthread_join and man 3 pthread_mutex_lock.
Practice: Cumulative#
- Four workers sum four disjoint ranges of one read-only array into four separate task structures.
mainjoins every worker before adding the fourresultfields. Identify which memory is shared, which writes can overlap safely, and what ordering makes the final reads safe. - Two fields,
itemsandtotal_cost, must always describe the same shopping basket. Give a locking rule for one writer and one reader, and explain why protecting only the writer is insufficient.
Note
- Cumulative Concurrency Answers
9. The array and task array are shared. Concurrent reads of the input array are safe, and each worker writes a distinct result object, so no two threads conflict on one location. Each successful pthread_join orders that worker's completed writes before main reads its result.
10. Both the writer's compound update and the reader's pair of reads must hold the same mutex. Otherwise the reader can run between the two writes and observe an items value from one state with a total_cost value from another; locking only writers prevents writer-writer overlap but does not exclude an unprotected reader.
One important shared resource from the opening list is the process's file-descriptor table. If one thread opens or closes a descriptor, the change belongs to the process, not only to that thread. Threads using the same open descriptor also interact with the same kernel-managed open-file state, including its current offset, so their I/O may need coordination just like shared-memory updates. File Systems now develops what descriptors, offsets and open files actually represent.