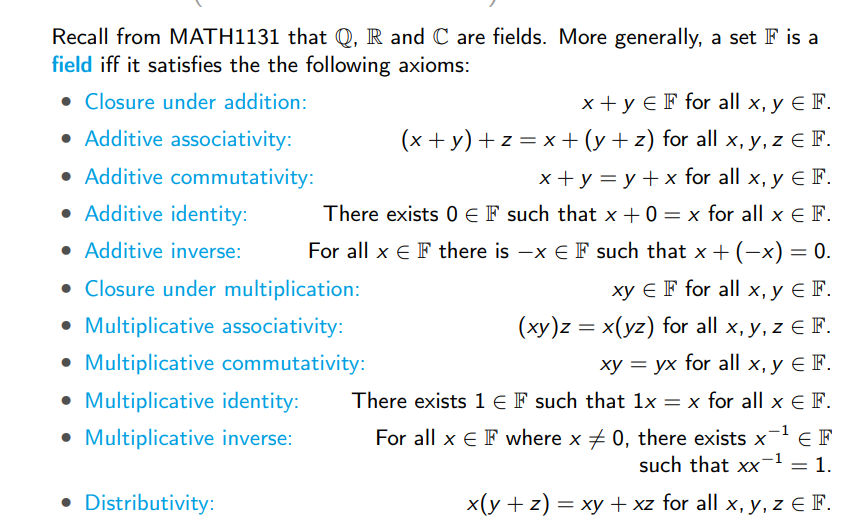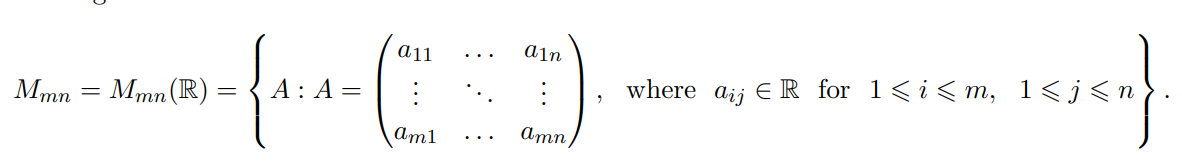To define a vector space, we need a mathematical system which consists of the following four things:
A set V of elements called "vectors".
A "vector-addition" rule that combines a pair of vectors from V. This is usually just represented by a +. For vectors v,w∈V, you combine them by doing v+w.
A field of scalars, denoted by F, where F could denote the rational numbers Q or the real numbers R or the complex numbers C. There are other less common examples too.
A "multiplication by a scalar" rule for combining a vector from V and a scalar from F to form a vector. This is probably the most confusing one.
Basically, from the previous 3 rules, you can discern that a vector can have many possible forms (i.e. made up of only 1s and 0s, or of 2 dimensional matrices etc.), hence, a proper way of determining what happens when scalars multiply such vectors must be formed. There cannot be a default way for every vector as its contents may or may not be different per vector type.
If λ is a scalar and v is an element of V, then λ∗v means the result of multiplying v by the scalar λ.
You can internalise this using these examples:
Standard Rule: If V is a 2D coordinate space and F is the real numbers, the rule is λ∗(x,y)=(λx,λy).
Matrix Rule: if V is a set of 2×2 matrices, multiplying by a scalar means applying it to all four entries inside the matrix grid.
Function rule: If V is a set of functions, then multiplying a function f(x) by a scalar λ creates a brand new function g(x), defined by the rule g(x)=λ⋅f(x).
The system is then denoted by (V,+,∗,F). Often times we can omit the ∗ if its representation remains obvious.
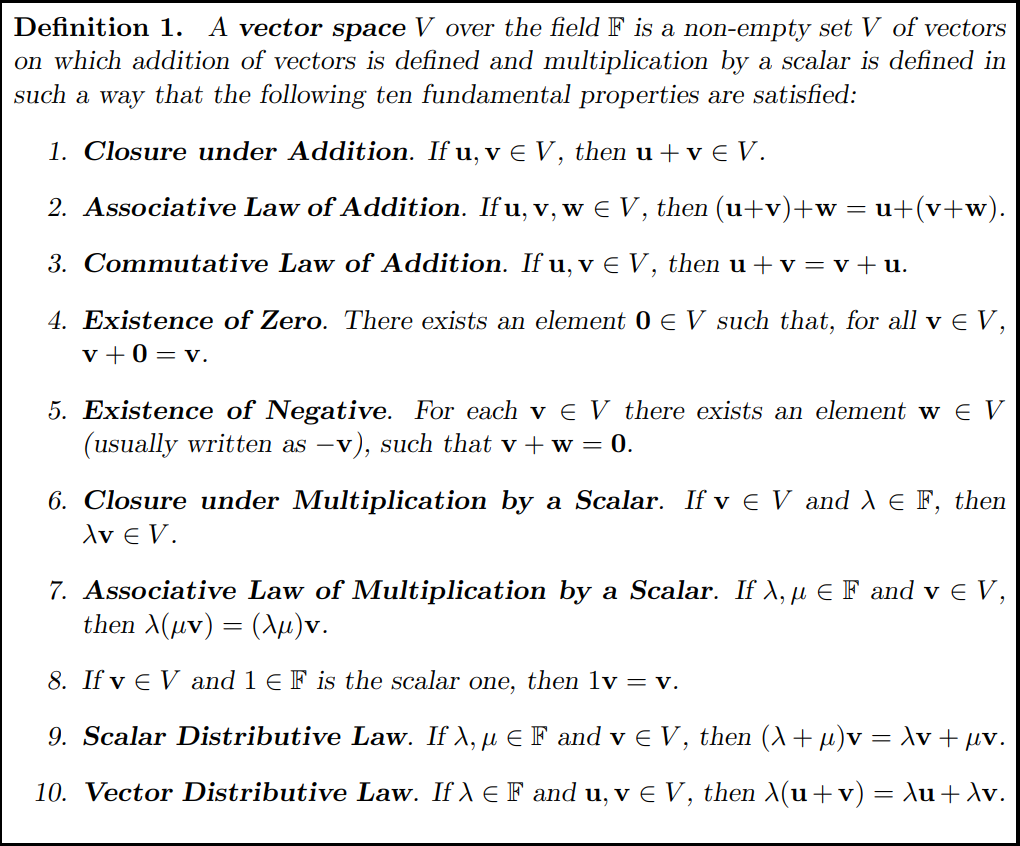
We can now give a formal definition of a vector space.
Note:
1. Each of the basic rules is called an axiom
2. The vector −v in axiom 5 and the vector formed by multiplying v with the scalar -1 are not the same by definition.
3. Formally, axiom 7 says λ∗(μ∗v)=(λμ)∗v.
4. In axiom 9, the addition on the left is the addition of two scalars while the addition on the right is the addition of two vectors. They are different additions.
5. Two vector spaces are only the same when all the four things are the same (V,+,∗,F). However, different vector spaces with the same set of vectors are rarely discussed, unlike different sets of vectors with the same set of scalars and the same operations.
6. When there is no confusion, we shall simply call (V,+,∗,F), the vector space V.
It is very difficult from the definition alone to acquire a good intuitive understanding - a "gut feeling" - for what is meant by a vector space. You need to supplement the definition by a good “rough idea” of what a vector space is. A good rough idea could be:
A vector space is “something where we know how to add objects and multiply objects by numbers, and where the addition and multiplication satisfy ‘sensible’ laws”
Example 1 (The Vector Space Rn). This represents the set of all vectors of all reals in any nth dimension.
Rn=⎩⎨⎧x:x=x1⋮xn for x1,…,xn∈R⎭⎬⎫.
The set of scalars is simply R.
Vector addition is then defined by
x1⋮xn+y1⋮xn=x1+y1⋮xn+yn.
To prove that it is a vector space, it is necessary to show that all ten axioms listed in the definition are satisfied by the system.
All the axioms are general statements about arbitrary vectors and scalars. We have to prove the axioms are satisfied by any:
u=u1⋮un,v=v1⋮vn,w=w1⋮wn, and λ,μ∈R.
Lot's of working out to prove all 10 axioms
After we have checked that all ten axioms are satisfied, we can conclude that the system is a vector space, or simply Rn is a vector space over R.
Example 2 (The Vector Space Cn). The set of vectors similar to example 1 but in the field of the complex numbers.
To prove that this is a vector space it is necessary to show that the ten vector space axioms are satisfied. This proof is formally identical to that for Rn over R since only basic operations are involved.
Example 3 (The Vector Space Mmn=Mmn(R) of Real Matrices). This represents a vector made up of matrices of dimensions m,n where every number inside these matrices must be a real number (the scalar field F in this case). There is a natural and straightforward generalisation to Mmn(F), where the entries come from the field F.
Note
Lowk insane notation i couldnt be asked to latex
Example 4 (The Vector Space of Polynomials). This is simply the vector space representing every possible polynomial: x2,3x21+3,12+2x765+9x54355 etc. However it is worth noting that the set of all real-valued functions on R can form a vector space, as does the set of all continuous functions (so stuff like sin(x) or ex). To represent the set of all real polynomials, you write P(R).
A vector p∈P(R) is the polynomial given by p(x)=a0+a1x+⋯+anxn=∑k=0nakxk.
It is important to note that p(x) is not in considered a vector whilst p is. In other words, p is a real-valued function whilst p(x) is the value of the function at x.
One more thing to note is that P(R) has infinite dimensions since a polynomial can always have a higher leading coefficient since it is in the field of real numbers. You can generalise the field by simply denoting them as P(F) over a field F. I think any field with addition and multiplication by a scalar similarly defined is also a vector space.
For any non-negative integers n, the subset of all polynomial degrees n or less including the zero polynomial is again a vector space.
Pn(F)={p:p is a polynomial over F,degree of p≤n or p=0}.
Example 1 (Z3, the set of vectors with integer components)
This is simply represented by (x,y,z), and there are 2 axioms that this set breaks.
Since we have not specified the field of these vectors, the default field for scalar's is usually the real numbers R. Looking at Axiom 6, any vector multiplied by any scalar in the field must result in a vector that stays within the original set. However, suppose
λ=0.3,v=(1,2,3)
then, λv=(0.3,0.6,0.9), since this vector consists of at least one non-integer member, it cannot be in the original set, and thus the space is not closed.
Limiting the scalars to only consist of integers Z fixes our previous problem, however it breaks the very definition of . Since the integers don't have a multiplicative inverse (i.e. there does not exist a number z in the integers such that zz−1=1), you cannot choose a field to be integers only.
A vector space is fundamentally designed for continuous scaling; you need to be able to stretch or shrink a vector by any microscopic fraction. Because integers are rigid, whole steps, they can't handle being shrunk by fractions, which ruins the geometry required to be a true vector space.
Example 2 (The set of all matrices)
This set is obvious; suppose you have a matrice A23 and another matrice B32, attempting to add them is undefined, breaking the first axiom.
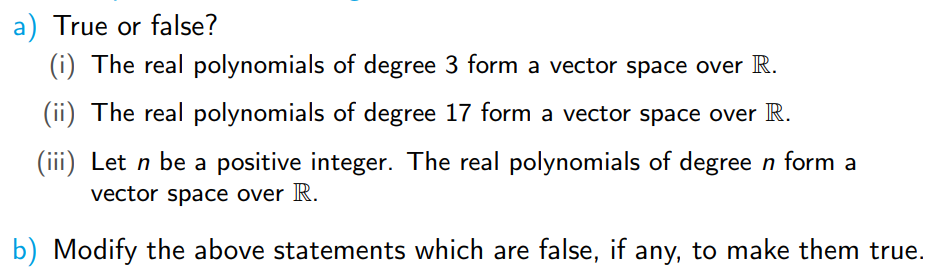
Example 3 (The set of polynomials of degree 3)
This seems like a 180, however, looking closely, the set consists of polynomials only of degree 3. Unlike the definition of Pn(F) which allows any polynomial with degree ≤n, the degree must be precisely n in this case. This violates Axiom 1 as:
let p(x)=x3+2x,let q(x)=−x3+5,p(x)+q(x)=2x+5
Since both p and q are within the set, performing an addition between the two results in a polynomial outside of the set, hence not being closed. We can generalise this to be true for any n.
The axioms give a minimal set of rules needed to define a vector space. The first five vector space axioms apply to vector addition, and they are in fact identical to the five basic axioms of addition for integers, real numbers and complex numbers. This means that all the arithmetic properties of vector addition are identical to corresponding properties of addition of numbers.
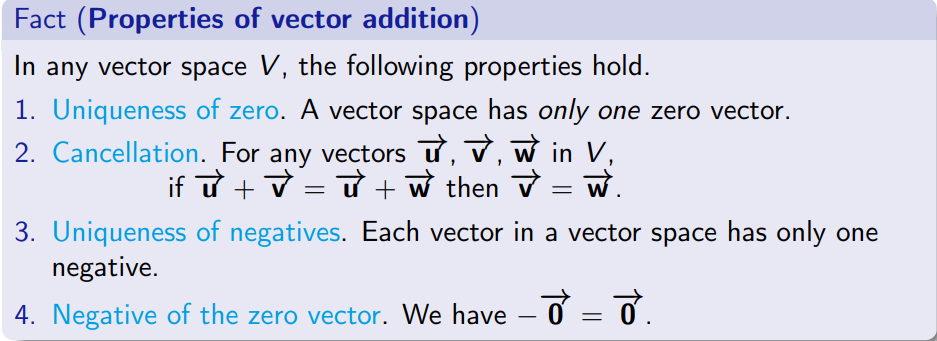
Proposition 1. In any vector space V, the following properties hold for addition.
Uniqueness of Zero. There is one and only one zero vector.
Cancellation Property. If u,v,w∈V satisfy u+v=u+w, then v=w.
Uniqueness of Negatives. For all v∈V, there exists only one w∈V such that v+w=0
Proof Prove (3): Each vector in a vector space only has one negative.
Let v+w=0 and v+u=0. By the axioms of a vector space, we can evaluate w as follows:
wwwww=w+0=w+(v+u)=(w+v)+u=0+u=u■.
Prove (4): The zero vector is its own negative i.e. 0=−0
By the existence of the zero vector, we know that adding 0 to itself yields:
0+0=0
By the definition of an additive inverse, the negative of the zero vector, −0, must satisfy:
0+(−0)=0
Since both expressions equal 0, we can equate them:
0+0=0+(−0)
Because the additive inverse is unique, it must follow that:
0=−0■.
Proposition 2. Suppose that V is a vector space over a field F, λ∈F, v∈F,0 is the zero scalar in F and 0 is the zero vector in V. Then the following properties hold for multiplication by a scalar:
Multiplication by the zero scalar.0v=0,
Multiplication of the zero vector.λ0=0.
Multiplication by −1.(−1)v=−v (the additive inverse of v).
Zero Products. If λv=0, then either λ=0 or v=0.
Cancellation Property. If λv=μv and v=0 then λ=μ.
Many problems about vectors involve subsets of some vector space, such as the points on a line in Rn forming a subset of Rn, or the points on a plane in R3 form a subset of Rn.
The question that arises is if a subset of the real-number line is a vector space; for now we will focus on ways to show that a given set is not a vector space.
Example. Suppose you have S=[−5,5]={x∈R:−5≤x≤5}, is this a vector space?
Geometrically, the set S represents a line segment.
The given system is not a vector space, since it is not closed under scalar multiplication. A counterexample; 5∈S, but 5 + 5 = 10 is not an element of S.
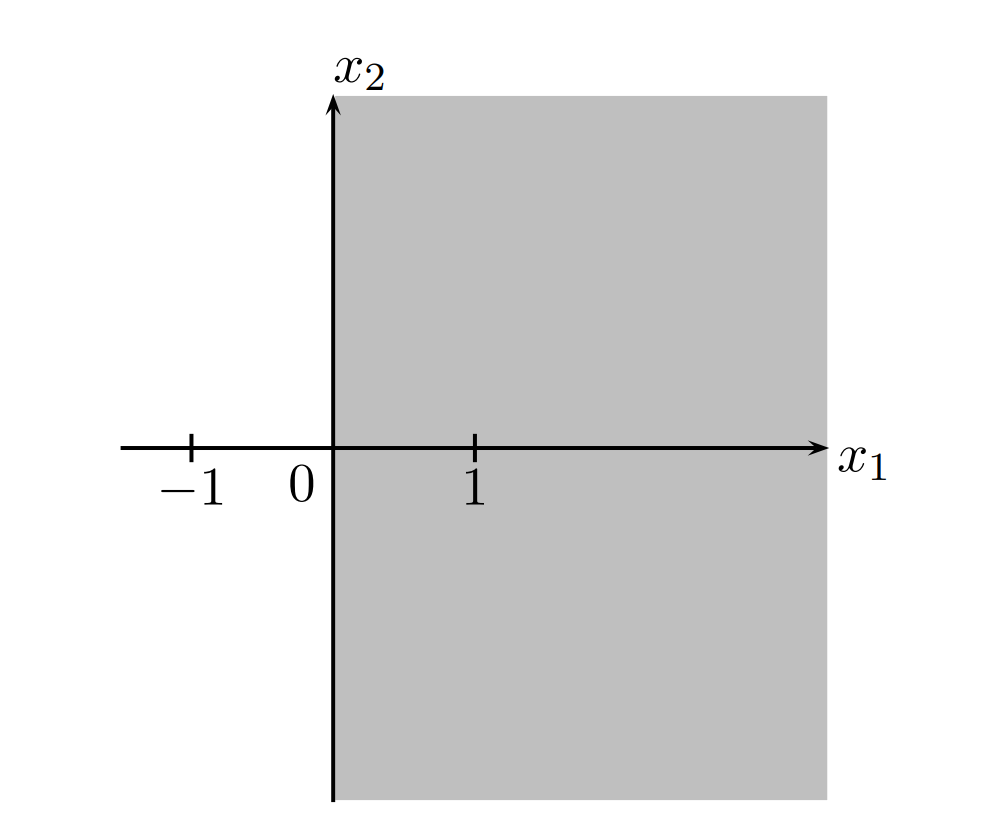
Example. The plane R2 is a vector space. Show that the subset S of R2 given by
S={x=(x1x2)∈R2:x1≥0}
is not a vector space.
There are several ways to solve this problem since there are several axioms which are not satisfied. One method is to note that (10)∈S, whereas −1(10)=(−10)∈/S. Hence the set S is not closed under scalar multiplication and so S is not a vector space. Geometric view of S
Example. Let S=p∈P(R):p(2)≥0. Is S a vector space?
Suppose p(x)=x2, then p∈S as p(2)=4≥0, but −p is not in S as −p(2)=−4, therefore S is not a vector space.
A common theme here is in showing that a set does not need to contain some region (i.e. negatives), you should always give a specific numerical example. You should do the same when showing that a set is not closed under addition, or not closed under scalar multiplication.
However, you can (sometimes) use these methods to show that something is not a vector space, but you can never use them to show that something is a vector space; (basically some vs all proof in 1081).
So far we have seen that it is usually fairly simple to show that a subset is not a vector space, but it will be time-consuming and tedious to show that a given subset is a vector space by checking all ten axioms. We can leverage the fact that they are subsets to make things simpler.
We first make the following definitions,
Note
Definition
A subset S of a vector space V is called a subspace of V if S is itself a vector space over the same field of scalars as V and under the same rules for addition and multiplication by scalars.
In addition if there is at least one vector in V which is not contained in S, the subspace S is called a proper subspace of V.
A simple test for a subspace is given by the following theorem.
Note
The Subspace Theorem
A subset S of a vector space V over a field F, under the same rules for addition and multiplication by scalars, is a subspace of V if and only if
i) The vector 0 in V also belongs to S
ii) S is closed under vector addition, and
iii) S is closed under multiplication by scalars from F.
Proof. If S is a subspace then it is a vector space.
Suppose S contains the zero vector and the two closure axioms 1 and 6 are satisfied by elements of S. Since V is a vector space, and S and V are under the same operations, the vector space axioms 2, 3, 7, 8, 9, 10 are automatically satisfied by all elements of S.
Since S contains the zero vector, if v∈S, then 0+v=0 (since this is true in V and hence in S, so axiom 4 follows).
Finally, if v∈S then v∈V . Hence, from part 3 of Proposition 2, we have −v=(−1)v. But, as S is closed under multiplication by a scalar, we have (−1)v∈S, and hence −v∈S. Thus, axiom 5 is satisfied for all vectors in S. The proof is complete.
If we want to check if S is a subspace of V, we should first check if the zero vector of V is in S. If the zero vector is in S we can proceed to verify the two closure axioms. Otherwise, we can draw a conclusion that S is not a subspace of V. If we have proved that axioms 1, 4 and 6 are true, then axiom 5 also works automatically and need not be checked separately.
In order to use the subset theorem, you will need to identify a vector space containing your set S.
This is where to look: In all the sets below, m and n are positive integers and F is a field. Usually, F is Q, Ror C. Recall:
Rn is a vector space over the field R.
Cn is a vector space over the field C (and also over the field R).
P(F), the set of polynomials with coefficients in the field F, is a vector space over F.
Pn(F), the set of polynomials of degree at most n with coefficients in the field F, is a vector space over F.
Mmn(F), the set of matrices with m rows and n columns and with entries in the field F, is a vector space over F.
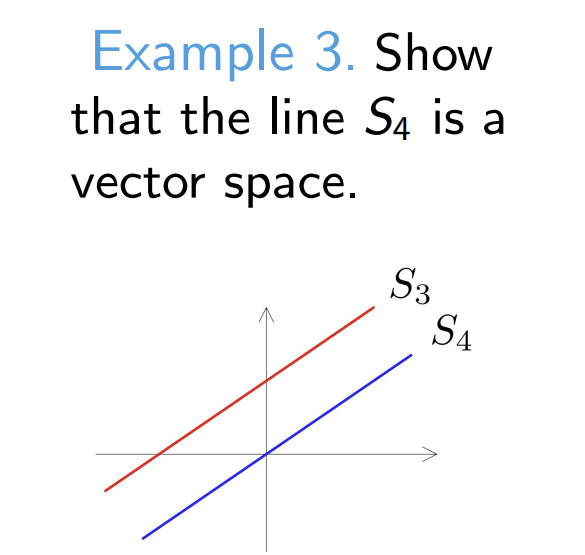
Example.
Proof. Since S4 is a subset of the known vector space R2, we only need to verify the three conditions of the Subspace Theorem to prove it is a vector space.
1. The zero vector is in S4:
Let x=(00). We test if it satisfies the rule of the set by substituting x1=0 and x2=0:
2(0)−3(0)=0
Since the condition is satisfied, the zero vector 0∈S4.
2. Closure under addition:
Let u and v be two random vectors in S4. By definition of the set, this means we know as a fact that 2u1−3u2=0 and 2v1−3v2=0.
We want to test if their sum, u+v=(u1+v1u2+v2), also satisfies the rule of the set.
Because the result is 0, the sum vector survives the test, meaning u+v∈S4.
3. Closure under scalar multiplication:
Let u∈S4 (so 2u1−3u2=0) and let λ be any real scalar.
We want to test if the scaled vector, λu=(λu1λu2), satisfies the rule.
Because the result is 0, the scaled vector survives the test, meaning λu∈S4.
Because S4 contains the zero vector and is closed under both addition and scalar multiplication, it is a valid subspace of R2, and therefore it is a vector space itself. ■.
Example. Show that S={x∈R2:2x1−3x2=0} is a vector space. Proof. We can rewrite the equation 2x1−3x2=0 as x2=32x1, and then let S be the subset of R2 defined by vectors of the form (x32x) where x∈R. We can then verify the three subspace conditions.
1. The zero vector is in S:
If we choose x=0, the resulting vector in our set is:
(032(0))=(00)
Since we can generate the zero vector, 0∈S.
2. Closure under addition:
Let u and v be two vectors in S. By definition of the set, they must have the form:
Notice that the bottom component is exactly 32 times the top component. Because the sum perfectly matches the required pattern of the set, u+v∈S.
3. Closure under scalar multiplication:
Let u=(a32a) be in S, and let λ be any real scalar.
We scale the vector:
λu=λ(a32a)=(λaλ(32a))=(λa32(λa))
Once again, the bottom component is exactly 32 times the top component. The scaled vector maintains the pattern, so λu∈S.
Since S contains the zero vector and is closed under addition and scalar multiplication, it is a subspace of R2.
You can do it both ways; you can rewrite a given equation into a vector form or you can simply just use the equation as in previous examples.
Lemma. A line in Rn is a subspace if and only if it passes through the origin;
Suppose that S represents a line in Rn. If 0∈/S, then S is not a subspace. Hence, a line which does not pass through the origin is not a vector subspace.
If S is a line through the origin we can write
S={x∈Rn:x=tv,t∈R},
where v is a fixed non-zero vector in Rn. To check if S is a subspace we check the two closure axioms. Closure under addition. If x1,x2∈S then
x1=t1vandx2=t2vfor some t1,t2∈R.
Hence,
x1+x2=(t1+t2)v=t′v,
where t′=t1+t2∈R. Thus, x1+x2∈S, and hence S is closed under addition. Closure under multiplication by a scalar. We have
x=tvfor somet∈R,
and hence, if λ∈R,
λx=λ(tv)=(λt)v=t′′v,
where t′′=λt∈R. Hence λx∈S, and thus S is closed under multiplication by a scalar.
Therefore, by the Subspace Theorem, the line S is a subspace of Rn if it passes through the origin. A similar result to that given for lines also holds for planes.
Example. Let S be the set of polynomials which satisfy all of the following conditions:
their coefficients are complex numbers,
their degree is at most 7,
their second derivative evaluated at x=5 is zero.
Is S a vector space over C?
Rewriting S in set notation,
S={p∈P7(C):p′′(5)=0}.
By the Subspace Theorem, we only check axioms 1, 4 and 6; Closure of vector addition:
Suppose p,q∈S, then p′′(5)=0,q′′(5)=0, if we let h=p+q, then
h′′(5)h′′(5)h′′(5)=p′′(5)+q′′(5)=0+0=0
meaning that vector addition is closed.
Closure under scalar multiplication:
Suppose p∈S, then p′′(5)=0, suppose c is some constant in C, and h(x)=c⋅p(x), so
Therefore, scalar multiplication is also closed (and hence negatives of vectors).
Existence of a 0 vector:
If p∈S, p′′(5)=0, but if p(x)=0 then p′′(5) is also equal to zero.
In practice, some of the most important subspaces of Rn are connected with systems of linear equations, that is, with the matrix equation Ax=b. Example. Let A be an m×n matrix with real entries. Show that the subset S of Rn which consists of all solutions of the matrix equation Ax=b for given b∈Rm is a subspace of Rn if and only if b=0.
Suppose there exists a case where b=0, then 0∈Rn is not a solution of Ax=b as A0=0=b, and hence S does not contain the zero vector. Thus S is not a subspace.
If b=0, then S is the set of solutions of Ax=0. We use the Subspace Theorem to show that S is a subspace. Closure under addition. If x∈S and y∈S, then Ax=0 and Ay=0, and hence
A(x+y)=Ax+Ay=0+0=0
Thus x+y∈S and S is closed under addition. Closure under multiplication by a scalar. If x∈S, we have Ax=0, and hence for all λ∈R,
A(λx)=λA(x)=λ0=0.
And hence is it closed under scalar multiplication.
Example. (Rapid-fire subspace drills) For each of the following sets, decide whether S is a subspace. Each one hides a different trap.
(a)S={x∈R3:x1+x2+x3=1}.
Not a subspace. Substituting the zero vector gives 0+0+0=0=1, so 0∈/S and we can stop immediately. Always test the zero vector first; if it fails you are done in one line.
(b)S={x∈R2:x1x2=0}, i.e. the union of the two coordinate axes.
Not a subspace. It contains 0, and it is even closed under scalar multiplication since (λx1)(λx2)=λ2x1x2=0; however it is not closed under addition:
(10)+(01)=(11)∈/S.
Passing two of the three conditions means nothing; all three must hold.
(c)S={x∈R3:x1=x2=x3}.
Subspace. Every element has the form t111 for t∈R, so S is a line through the origin, and we proved in the Lemma above that such lines are subspaces.
(d)S={A∈M22(R):det(A)=0}.
Not a subspace. The zero matrix is in S, and det(λA)=λ2det(A)=0 gives closure under scalar multiplication, but addition fails:
(1000)+(0001)=(1001),
and the identity matrix has determinant 1=0, so the sum has escaped the set.
The lesson from these drills: sets defined by linear, homogeneous conditions (like 2x1−3x2=0 or p′′(5)=0) tend to be subspaces, while sets defined by non-linear conditions (products, determinants, inequalities) or by conditions with a non-zero right hand side tend to fail.
An important theoretical and practical problem concerning vector spaces is that of finding all their subspaces. For example, it can be shown that the only subspaces of R2 are (1) the origin, (2) lines through the origin, and (3) R2 itself. Similarly, for R3 the only subspaces are (1) the origin, (2) lines through the origin, (3) planes through the origin, and (4) R3 itself. A listing of subspaces can be given for any vector space. However, before we can investigate this problem satisfactorily, we require further machinery. This machinery will be developed in Sections 6.4 and 6.5. In vector spaces other than Rn it may be difficult to get a good geometric feel for which subsets are subspaces. Nonetheless, the Subspace Theorem allows one a simple way to check whether a certain set is a subspace or not.
The two fundamental vector space operations are addition and multiplication by a scalar. If we combine these two we can result in something called "linear combinations" and "span"; a linear combination of a given set of vectors is a sum of scalar multiples of the vectors and the span of a given set of vectors is the set of all linear combinations of the vectors.
Note
Linear Combination
Let S={v1,⋯,vn} be a finite set of vectors in a vector space V over a field F. Then a linear combination of S is a sum of scalar multiples of the form
λ1v1+⋯+λnvn with λ1,⋯,λn∈F.>
Example. The vector (3−4) is a linear combination of the vectors in the set
{(11),(23),(1−1)} in R2 because (3−4)=2(11)+(−1)(23)+3(1−1).
Example. Is b=3−15 a linear combination of v1=111 and v2=1−12?
We are looking for scalars λ1,λ2 such that λ1v1+λ2v2=b. Comparing components gives three equations in only two unknowns:
λ1+λ2λ1−λ2λ1+2λ2=3,=−1,=5.
Adding the first two equations,
2λ1λ1=2=1,
and hence λ2=3−1=2. Substituting into the third equation as a check: 1+2(2)=5, which is consistent. Therefore
b=v1+2v2,
so b is a linear combination of the two vectors. Notice that if the third component of b were changed to, say, 4, the first two equations would still force λ1=1 and λ2=2, but then λ1+2λ2=5=4 and no combination would exist. This makes sense geometrically; in R3 the set of all linear combinations of two (non-parallel) vectors is only a plane, so most vectors miss it.
We know that a vector space is closed under addition and multiplication of scalars, and therefore any subspace of that vector space is closed as well, so it must be closed under the operation of forming linear combinations.
Note
Span
Let S={v1,⋯,vn} be a finite set of vectors in a vector space V over a field F. Then the span of the set S is the set of all linear combinations of S, that is,
span(S)=span(v1,⋯,vn)={v∈V:v=λ1v1+⋯+λnvn for some λ1,⋯λn∈F}.
Example. The span of a non-zero vector v in Rn is a line through the origin;
S={x∈Rn:x=λv, for some λ∈R}.
This set is just span(v).
Example. If {v,w} is a pair of non-zero, non-parallel vectors in Rn then span(v,w) is a plane containing the origin.
Note
A span is a subspace
If S is a finite, non-empty set of vectors in a vector space V, then span(S) is a subspace of V. Further, span(S) is the smallest subspace containing S (in the sense that span(S) is a subspace of every subspace which contains S).
Proof. We first note that 0∈S, since we may take each scalar to be zero. We know that every linear combination of S is a vector in V, so span(S) is a subset of V.
To prove that span(S) is a subspace we will use the Subspace Theorem, so we set out to prove that span(S) is closed under addition and under multiplication by scalars. Let S be the set
S={v1,…,vn}
where all vj belong to V.
To show closure under addition, suppose u,w∈span(S). Then
uwsou+w=λ1v1+⋯+λnvnfor some λ1,…,λn∈Fand=μ1v1+⋯+μnvnfor some μ1,…,μn∈F,=(λ1+μ1)v1+⋯+(λn+μn)vnwith λ1+μ1,…,λn+μn∈F.
This shows that u+w belongs to span(S), so span(S) is closed under addition. To prove closure under multiplication by a scalar, suppose u∈span(S) and λ∈F. Then
λu=λ(λ1v1+⋯+λnvn)=(λλ1)v1+⋯+(λλn)vn,
where λλ1,…,λλn∈F. This shows that λu belongs to span(S), so span(S) is closed under multiplication by scalars.
We have now proved that span(S) is a subspace of V. To show that it is the smallest subspace of V containing S, suppose W is any subspace of V containing S. Then W is itself a vector space containing S and, by what we have just proved, span(S) is a subspace of W. This completes the proof by showing that span(S) is a subspace of every subspace of V containing S.
Note
Definition 3.
A finite set S of vectors in a vector space V is called a spanning set for V if span(S) = V or equivalently, if every vector in V can be expressed as a linear combination of vectors in S.
Example. Every vector x1⋮xn∈Rn can be written as x=x1e1+⋯+xnen. This expresses x as a linear combination of the set {e1,⋯,en}, where
e1=10⋮0,e2=01⋮0,⋯,en=00⋮1.
Thus, Rn= span$(\mathbf{e}_1,\cdots,\mathbf{e}_n)$ and the set {e1,⋯,en} spans Rn.
Example. Let Pn denote the space of polynomials of degree less than or equal to n. Every polynomial p∈Pn can be written as a linear combination of the polynomials {1,x,x2,⋯,xn}, so Pn=span(1,x,x2,⋯,xn) . We shall see later that there is no finite set of vectors whose span is all of P (the vector space of all polynomials).
We want to have an effective way to tell whether or not a given vector in Rm belongs to the span of a set S={v1,…,vn}. From the definition of span, we know that b belongs to span(S) if and only if there are λ1,…,λn∈R such that
b=λ1v1+⋯+λnvn.
This equivalent to the condition that there is at least one solution to the vector equation
x1v1+⋯+xnvn=b,
where x1,…,xn are the unknowns. This vector equation represents a set of simultaneous linear equations in n unknowns. Therefore the question of whether b belongs to span(S) is a question of whether or not a particular set of linear equations has a solution. This is the sort of question which we studied in detail in MATH1131/41.
Furthermore, suppose that v1=a11⋮am1, v2=a12⋮am2, …, vn=a1n⋮amn, and x=x1⋮xn.
If that A is the m×n matrix whose columns are the vectors v1,…,vn then
Proposition 3 (Matrices, Linear Combinations and Spans). If S={v1,…,vn} is a set of vectors in Rm and A is the m×n matrix whose columns are the vectors v1,…,vn then
a) a vector b in Rm can be expressed as a linear combination of S if and only if it can be expressed in the form Ax for some x in Rn,
b) a vector b in Rm belongs to span(S) if and only if the equation Ax=b has a solution x in Rn.
If we call this last vector b, then x=113 is a solution of Ax=b precisely because b can be written as the linear combination v1+v2+3v3.
Ax is a linear combination of the columns of A, with the entries of x as the scalars.
This one observation powers the rest of the chapter. A useful special case: if ej is the jth standard basis vector in Rn, then Aej=aj, the jth column of A, since every scalar in the combination is 0 except the jth, which is 1.
Since the span of the columns of a matrix comes up constantly, it gets its own name.
Note
Definition 4
The subspace of Rm spanned by the columns of an m×n matrix A is called the column space of A and is denoted by col(A).
Basically, col(A) is the set of every output Ax that the matrix could ever produce; asking "is b∈col(A)?" is exactly asking "does Ax=b have a solution?".
By Proposition 3, every span question in Rm turns into a question about linear equations:
b∈span(S)⟺Ax=b has a solution,
where A is the matrix whose columns are the vectors in S. So the method is always the same: build A, form the augmented matrix (A∣b), reduce to row-echelon form, and read off whether the system is consistent. If the right-hand column is non-leading, a solution exists; if the right-hand column is leading, there is no solution.
Example. Is the vector b=1412 in the span of the set S=⎩⎨⎧1342,−4−8−126⎭⎬⎫?
In geometric terms, we are asking whether the point (1,4,1,2) lies on the plane through the origin parallel to the two vectors in S. Let A be the matrix whose columns are the members of S, and reduce the augmented matrix (A∣b) to row-echelon form:
The third row reads 0=−4, which is impossible; the right-hand column is a leading column, so the system has no solution. Therefore b does not belong to span(S).
Example. Find conditions which are necessary and sufficient for a vector b∈R3 to belong to the span of S={v1,v2,v3}, where
v1=123,v2=11−1,v3=−105.
Hence determine whether v=21−1∈span(S), and give a geometric interpretation of the span.
This time we keep a general right hand side b and row-reduce:
The last row says 0=5b1−4b2+b3, so the system has a solution if and only if
5b1−4b2+b3=0,
and this is the condition for b∈span(S). To test v, substitute its components into the condition;
5(2)−4(1)+(−1)=10−4−1=5=0,
so v∈/span(S). Geometrically, the condition is the Cartesian equation 5x1−4x2+x3=0 of a plane through the origin with normal 5−41; the span of the three vectors is exactly this plane. Notice how the span of three vectors collapsed to a plane rather than filling all of R3 — this is a preview of linear dependence, coming in 6.5.
As a sanity check, each of v1,v2,v3 belongs to the span and therefore should satisfy the condition itself; for v1 we get 5(1)−4(2)+3=0 as expected, and you can check the other two.
Example. Determine whether or not the set S={v1,v2,v3,v4} is a spanning set for R3, where
v1=123,v2=11−1,v3=−105,v4=235.
S is a spanning set for R3 if and only if the system Ax=b has a solution for everyb∈R3. Row-reducing the augmented matrix,
The last row now has the leading entry 3 in the fourth column, so the right-hand column is non-leading no matter what b is; the system always has a solution. Hence every b∈R3 belongs to span(S), and S is a spanning set for R3. Compare this with the previous example; the extra vector v4 is what saved us from the plane.
Note that the third column of the row-echelon form is non-leading, and the system would still be solvable for every b if that column were deleted. This means v3 can be dropped and {v1,v2,v4} still spans R3. In general:
If the ith column of the row-echelon form is non-leading, then deleting vi from S leaves the span unchanged.
Example. (Spans outside Rn) Find conditions on the coefficients of p∈P3(R) so that p∈span(1+x,1−x2).
Let p(x)=b0+b1x+b2x2+b3x3. Then p∈span(1+x,1−x2) if and only if there exist λ1,λ2∈R such that, for all x∈R,
p(x)=λ1(1+x)+λ2(1−x2)=(λ1+λ2)+λ1x−λ2x2.
Two polynomials are equal for all x if and only if all their corresponding coefficients are equal, so comparing coefficients of 1,x,x2,x3:
The system has a solution if and only if b0−b1+b2=0 and b3=0, so these are the conditions for p to belong to span(1+x,1−x2). The method is identical to the Rm case; comparing coefficients is what converts polynomials into columns of numbers.
Example. (Exam-style twist: an unknown inside the vector) For which value(s) of k does b=1k3 belong to span111,012?
Set up the augmented matrix exactly as before; the unknown k simply rides along in the right-hand column.
Therefore b∈span(S) exactly when k=2, in which case back substitution gives λ2=k−1=1 and λ1=1, i.e. b=v1+v2. The decision here is realising that a condition question and a membership question are the same computation; you row-reduce with the unknown in the augmented column and force consistency at the end.
Suppose that v1,v2 are non-zero vectors. We saw in first year that span(v1,v2) represents a plane if v1 and v2 are not parallel, but only a line if they are parallel. Similarly, for three non-zero vectors in R3, span(v1,v2,v3) represents
i) a line if the three vectors are all parallel,
ii) a plane if they are coplanar, or
iii) the whole of R3 otherwise.
Linear independence is the machinery that makes this "collapsing span" behaviour precise in any vector space.
Note
Definition 1
Suppose that S={v1,…,vn} is a subset of a vector space. The set S is a linearly independent set if the only values of the scalars λ1,λ2,…,λn for which
λ1v1+⋯+λnvn=0
are λ1=λ2=⋯=λn=0.
Note
Definition 2
The set S={v1,…,vn} is a linearly dependent set if it is not a linearly independent set; that is, if there exist scalars λ1,…,λn, not all zero, such that
λ1v1+⋯+λnvn=0.
Basically, choosing every scalar to be zero always produces 0, so that tells you nothing; independence says this trivial choice is the only way to produce 0. A dependent set carries redundancy — some vector in it can be manufactured out of the others, so it contributes nothing new to the span. The zero linear combination always exists; the entire question is whether it is unique.
Example. Show that the vectors 1234 and −3−6−95 form a linearly independent set.
Applying the definition, we look for scalars λ1,λ2 such that λ1v1+λ2v2=0. Comparing components gives four equations:
λ1−3λ22λ1−6λ23λ1−9λ24λ1+5λ2=0,=0,=0,=0.
Each of the first three equations says exactly the same thing, namely λ1=3λ2. Substituting into the fourth,
4(3λ2)+5λ217λ2λ2=0=0=0,
and hence λ1=3(0)=0. The only solution is the zero one, so the two vectors form a linearly independent set.
Example. (Geometric meaning for pairs) Two non-zero vectors in Rn are parallel if and only if they form a linearly dependent set.
Suppose first that {v1,v2} are parallel, so v2=λv1 for some non-zero λ∈R. Rearranging gives λv1−v2=0, and the coefficient of v2 is −1=0, so the set is linearly dependent.
Conversely, if the set is dependent then λ1v1+λ2v2=0 with not both scalars zero. Without loss of generality λ1=0, so
v1=−λ1λ2v2,
which shows v1 is a scalar multiple of v2; also λ2=0 (otherwise v1 would be 0), so the multiple is non-zero and the vectors are parallel.
Example. It is easy to verify, component by component, that
3121+21−12+(−1)547=000,
so by Definition 2 this set of three vectors is linearly dependent. Notice that no two of the three vectors are parallel. For three or more vectors, checking pairs is not enough — dependence of a triple means coplanarity, and a single non-zero combination summing to 0 is all it takes.
Just as span questions became existence questions for Ax=b, independence questions become uniqueness questions for the homogeneous system Ax=0.
Note
Proposition 1 If S={a1,…,an} is a set of vectors in Rm and A is the m×n matrix whose columns are the vectors a1,…,an, then the set S is linearly dependent if and only if the system Ax=0 has at least one non-zero solution x∈Rn.
Proof. Since Ax=x1a1+⋯+xnan, a non-zero solution of Ax=0 is precisely a choice of scalars, not all zero, making the linear combination equal to 0; this is word for word the definition of linear dependence. ■
In practice, since row operations never change a zero right-hand column, we can drop the augmented column entirely and just reduce A to a row-echelon form U. Then
all columns of U leading⟺S independent,some column non-leading⟺S dependent.
Example. Is the set S=⎩⎨⎧1324,−2−102,0012⎭⎬⎫ a linearly independent set?
Let A be the matrix whose columns are the vectors in S, and reduce:
There are no non-leading columns, so the only solution of Ax=0 is x=0, and hence S is linearly independent.
Example. Suppose v1=123, v2=11−1, v3=−105 and v4=235 (the same set that spanned R3 in 6.4.2).
a) Prove that S={v1,v2,v3,v4} is a linearly dependent set.
b) Find all possible ways of writing 0 as a linear combination of the vectors in S.
c) Find a linearly independent subset of S with the same span as S.
a) We already reduced this matrix in 6.4.2:
A=12311−1−105235⟶U=1001−10−1202−13.
The third column of U is non-leading, so Ax=0 has infinitely many solutions, and in particular non-zero ones. Therefore S is linearly dependent. (Alternatively: four vectors could never be independent in R3; see Theorem 3 of 6.6.2 later.)
b) Back substitution with x3=λ free: the third row gives 3x4=0, so x4=0; the second row gives
−x2+2λ−0x2=0=2λ;
and the first row gives
x1+2λ−λ+0x1=0=−λ.
Hence every way of writing 0 is of the form
λ(−v1+2v2+v3)+0v4=0,λ∈R.
c) Choosing λ=1 gives −v1+2v2+v3=0, i.e.
v3=v1−2v2,
so v3 is redundant and span(v1,v2,v4)=span(S). Removing the third column from A and reducing,
12311−1235⟶1001−102−13,
which has no non-leading columns, so {v1,v2,v4} is a linearly independent subset of S with the same span as S.
Example. (Polynomials) Show that the set {1+x,2−x} is linearly independent in P(R).
Suppose that λ1(1+x)+λ2(2−x)=0 for all x∈R. Expanding,
(λ1+2λ2)+(λ1−λ2)x=0,
and since a polynomial is the zero polynomial only when every coefficient vanishes,
λ1+2λ2λ1−λ2=0,=0.
Subtracting the second equation from the first gives 3λ2=0, so λ2=0 and then λ1=0. The only solution is the zero one; the set is linearly independent.
Example. Is the set {1+x,2−x,−1+2x} a linearly independent subset of P(R)?
Suppose λ1(1+x)+λ2(2−x)+λ3(−1+2x)=0 for all x∈R. Comparing coefficients,
λ1+2λ2−λ3λ1−λ2+2λ3=0,=0.
This is a homogeneous system of two equations in three unknowns, so its row-echelon form
(102−3−13)
must have a non-leading column (the third). There are therefore non-zero solutions, and the set is linearly dependent. Back substitution with λ3=1 gives λ2=1 and λ1=−1, and indeed
−1(1+x)+1(2−x)+1(−1+2x)=0for all x∈R.
Although finding the explicit combination was not required, it is a very cheap way to check your row reduction.
Example. (Out of the box: functions) Show that {sinx,cosx} is a linearly independent subset of the vector space of real-valued functions on [−π,π], but that {1,sin2x,cos2x} is linearly dependent.
For functions, the equation λ1f1+⋯+λnfn=0 must hold for allx, and this gives two lines of attack:
to prove independence, plug in enough specific x values to force all the scalars to zero;
to prove dependence, produce a known identity connecting the functions.
For {sinx,cosx}: suppose λ1sinx+λ2cosx=0 for all x∈[−π,π]. Substituting x=0,
λ1sin0+λ2cos0λ2=0=0,
and substituting x=2π,
λ1sin2π+λ2cos2πλ1=0=0.
Both scalars are forced to zero, so the set is linearly independent.
For {1,sin2x,cos2x}: the Pythagorean identity rearranges to
(−1)⋅1+1⋅sin2x+1⋅cos2x=0for all x,
which is a linear combination with scalars −1,1,1 (not all zero) equal to the zero function. The set is linearly dependent. A set of functions can look completely unrelated and still be dependent through an identity — trig sets like this one are a classic exam trap.
The following theorem is one of the main reasons linear independence matters.
Note
Theorem 2 (Uniqueness of Linear Combinations) Let S be a finite, non-empty set of vectors in a vector space and let v be a vector which can be written as a linear combination of S. Then the values of the scalars in the linear combination for v are unique if and only if S is a linearly independent set.
Basically, an independent set gives every vector in its span exactly one "recipe"; a dependent set gives infinitely many recipes for anything it can make at all.
Proof. It is easier to prove the equivalent statement: the scalars are non-unique if and only if S is linearly dependent. Suppose v has two different expressions
v=λ1v1+⋯+λnvnandv=μ1v1+⋯+μnvn.
Subtracting the second from the first,
(λ1−μ1)v1+⋯+(λn−μn)vn=0,
and since the two expressions differ, at least one coefficient λj−μj is non-zero; hence S is dependent. Conversely, if S is dependent then there are scalars α1,…,αn, not all zero, with α1v1+⋯+αnvn=0, and adding this "hidden zero" onto any expression for v produces a genuinely different second expression,
v=(λ1+α1)v1+⋯+(λn+αn)vn.■
Example. With S={v1,v2,v3,v4} the linearly dependent set from the previous section, show that b=77−4 belongs to span(S), and check that the linear combination for b is not unique.
The right-hand column is non-leading, so a solution exists and b∈span(S); but the third column is also non-leading, so there are infinitely many solutions and hence infinitely many expressions for b as a linear combination of S. Explicitly, back substitution with x3=λ gives x4=1, x2=6+2λ and x1=−1−λ, so
77−4=(−1−λ)v1+(6+2λ)v2+λv3+v4for every λ∈R.
If we drop v3 (the vector belonging to the non-leading column) and use the independent set {v1,v2,v4} instead, the combination becomes unique; setting λ=0 above,
We have seen concrete examples of spans collapsing when the spanning vectors are dependent. The general results are collected here; they are the bridge into bases and dimension in 6.6.
Note
Theorem 3 A set of vectors S is a linearly independent set if and only if no vector in S can be written as a linear combination of the other vectors in S, that is, if and only if no vector in S is in the span of the other vectors in S.
Equivalently: S is dependent if and only if at least one vector in S is in the span of the others. This is really just a restatement of the definition; if λ1v1+⋯+λnvn=0 with some λi=0, we can solve for vi in terms of the rest, and conversely if vi=μ1v1+⋯+μi−1vi−1+μi+1vi+1+⋯+μnvn then moving vi across gives a non-trivial combination equal to 0 (its coefficient is −1).
Example. For the dependent set {v1,v2,v3,v4} from 6.5.1 we found v3=v1−2v2, so v3∈span(v1,v2). Rearranging the same relation also gives v1∈span(v2,v3) and v2∈span(v1,v3). However v4 is not in the span of the other three (its coefficient in every dependence relation was 0). Geometrically: v1,v2,v3 all lie in one plane, and v4 sticks out of it. A dependent set does not mean that every vector is redundant — only that at least one is.
Note
Theorem 4 If S is a finite subset of a vector space V and the vector v is in V, then
span(S∪{v})=span(S)if and only ifv∈span(S).
Basically, adding a vector you could already build changes nothing; adding a vector you could not build genuinely enlarges the span. Combining Theorems 3 and 4:
If S is linearly dependent, you can drop at least one vector from S without changing the span; if S is linearly independent, dropping any vector strictly shrinks the span.
In formal terms:
Note
Theorem 5 Suppose that S is a finite subset of a vector space. The span of every proper subset of S is a proper subspace of span(S) if and only if S is a linearly independent set.
Example. For our running set, span(v1,v2,v3,v4)=span(v1,v2,v4)=R3, and {v1,v2,v4} is linearly independent; dropping any further vector leaves only a plane, not all of R3, exactly as Theorem 5 predicts.
One more result, needed for the construction of bases in the next section.
Note
Theorem 6 If S is a finite linearly independent subset of a vector space V and v is in V but not in span(S), then S∪{v} is a linearly independent set.
Proof. Let S={v1,…,vn} and suppose, for contradiction, that S∪{v} is dependent, so
λv+λ1v1+⋯+λnvn=0
with the scalars not all zero. If λ=0 then some λi=0, contradicting the independence of S. So λ=0, and dividing through by λ expresses v as a linear combination of S, contradicting v∈/span(S). Either way we hit a contradiction, so S∪{v} must be independent. ■
We have now met the two key properties a set of vectors can have: spanning (it can build everything) and linear independence (it builds things in only one way). A set with both properties is the best of both worlds — every vector in the space gets exactly one recipe — and such sets are so important that they get their own name.
Definition 1
A set of vectors B in a vector space V is called a basis for V if:
B is a linearly independent set, and
B is a spanning set for V (that is, span(B)=V).
(We exclude the vector space consisting of only the zero vector from this discussion.)
Basically, a basis is a minimal coordinate grid for V; big enough to reach everything, with no redundant directions. Too few vectors and you cannot span; too many and you lose independence.
Example. The set {e1,…,en} of standard basis vectors is a linearly independent spanning set for Rn (we saw both properties earlier), so it is a basis — the standard basis for Rn. Each vector a=a1⋮an is the unique linear combination a1e1+⋯+anen.
Example. Show that the set S=⎩⎨⎧210,−101,01−1⎭⎬⎫ is a basis for R3.
Let A be the matrix with the members of S as columns and reduce (A∣b) for a general b:
For every b∈R3 the right-hand column is non-leading, so Ax=b always has a solution and span(S)=R3. Moreover, the left side has no non-leading columns, so the only solution for b=0 is x=0 and S is linearly independent. Hence S is a basis for R3. One row reduction answers both basis conditions at once — never do two separate reductions.
Since a basis spans, every vector can be written as a linear combination of it; since a basis is independent, that combination is unique (Theorem 2 of 6.5.2). In summary:
Note
Unique representation property Let B={v1,…,vn} be a basis for a vector space V over F. Every vector v∈V can be written uniquely as
v=λ1v1+⋯+λnvn,λ1,…,λn∈F.
Example. Write b=−105 as the unique linear combination of the ordered basis ⎩⎨⎧v1=123,v2=11−1⎭⎬⎫ of span(v1,v2).
The leading columns are the first and second, so {v1,v2} spans the same set as S; and deleting the non-leading columns from the reduction shows {v1,v2} is independent. Hence {v1,v2} is a basis for span(S) (which is therefore a plane in R3).
Example. (Orthonormal bases) An orthonormal basis is a basis whose vectors all have length 1 and are mutually orthogonal, like {i,j,k} in R3. Orthonormality gives a shortcut for finding the scalars in a linear combination; if B={u1,…,un} is orthonormal and a=x1u1+⋯+xnun, then dotting both sides with ui kills every term except the ith, so
xi=ui⋅a.
For instance, B={u1,u2,u3} with
u1=210−21,u2=21021,u3=0−10
is an orthonormal basis for R3, and for a general a=a1a2a3,
so a=21(a1−a3)u1+21(a1+a3)u2−a2u3; no row reduction needed at all.
Example. The set {1,x,x2,…,xn} is a basis for Pn(R), called the standard basis for Pn(R). It spans by the very definition of a polynomial of degree at most n, and it is independent because λ1+λ2x+⋯+λn+1xn=0 for all x forces every coefficient to be zero.
We keep saying things like "a plane is two-dimensional". The following two theorems let us define dimension properly for any vector space with a finite basis.
Note
Theorem 1 The number of vectors in any spanning set for a vector space V is always greater than or equal to the number of vectors in any linearly independent set in V.
Basically, spanning sets are "big" and independent sets are "small", and they can only meet in the middle. (The proof reduces to the fact that a matrix with more rows than columns must produce a zero row in row-echelon form; we omit the details.)
Note
Theorem 2 If a vector space V has a finite basis, then every basis for V contains the same number of vectors.
Proof. Let B1 (with m vectors) and B2 (with n vectors) be bases for V. Then m≥n by Theorem 1, since B1 spans and B2 is independent; and n≥m by the mirror argument. Hence m=n. ■
Since the number of basis vectors does not depend on which basis you picked, the following definition makes sense.
Note
Definition 2
If V is a vector space with a finite basis, then the dimension of V, denoted by dim(V), is the number of vectors in any basis for V. Such a V is called a finite dimensional vector space.
Standard dimensions worth memorising (each comes from counting the standard basis):
dim(Rn)=n,dim(Pn)=n+1,dim(Mmn)=mn.
The +1 in dim(Pn)=n+1 trips everyone up at least once; the basis {1,x,…,xn} has n+1 elements because of the constant term. The space of geometric vectors in physical space has basis {i,j,k} and dimension 3, and we define the dimension of the zero vector space to be 0.
Note
Theorem 3 Suppose that V is a finite dimensional vector space. Then: 1. the number of vectors in any spanning set for V is greater than or equal to dim(V); 2. the number of vectors in any linearly independent set in V is less than or equal to dim(V); 3. if the number of vectors in a spanning set equals dim(V), the set is automatically linearly independent, and hence a basis; 4. if the number of vectors in a linearly independent set equals dim(V), the set is automatically a spanning set, and hence a basis.
Parts 3 and 4 are the workhorses. If you already know the dimension of the space, you only ever need to check one of the two basis conditions — the count does the other half for you.
Example. (Quick-fire applications of Theorem 3)
The two vectors (1−1) and (45) are non-parallel, hence linearly independent; since dim(R2)=2, part 4 says they form a basis for R2 with no spanning check needed.
A set of three vectors can never span R4, since dim(R4)=4>3 (part 1).
Any set of 10 vectors which spans R10 is a basis for R10 (part 3).
Any linearly independent set of 325 vectors in R325 is a basis for R325 (part 4).
A set of 1200 vectors in R1209 cannot be a spanning set, as 1200<1209.
Four polynomials can never be linearly independent in P2, since dim(P2)=3 (part 2).
Example. Show that the only subspaces of R3 are (1) the origin, (2) lines through the origin, (3) planes through the origin, and (4) R3 itself.
By part 2 of Theorem 3, no subspace of R3 can have dimension greater than 3, so the only possible dimensions are 0,1,2,3.
Dimension 0 is the subspace {0}, i.e. the origin.
A subspace of dimension 1 has the form span(v) with v=0, which is a line through the origin.
A subspace of dimension 2 has the form span(v1,v2) with {v1,v2} independent, which is a plane through the origin.
A subspace of dimension 3 has a basis of three independent vectors in R3; by part 4 that basis is a basis for R3 itself, so the subspace is all of R3.
This finally answers the question raised at the end of 6.3.
Two natural questions: does a basis always exist, and how do we actually compute one? The existence answers are:
Note
Theorem 4 If S is a finite non-empty subset of a vector space, then S contains a subset which is a basis for span(S). In particular, every non-zero vector space which can be spanned by a finite set has a basis.
Note
Theorem 5 Suppose that V is a vector space which can be spanned by a finite set of vectors. If S is a linearly independent subset of V, then there exists a basis for V which contains S as a subset; i.e. every linearly independent set can be extended to a basis.
The ideas behind the proofs are simple. For Theorem 4, keep throwing away redundant vectors (Theorem 5 of 6.5.3 guarantees one exists while the set is dependent) until what remains is independent; the span never changes and the process must stop because S is finite. For Theorem 5, keep adjoining vectors from outside the current span (Theorem 6 of 6.5.3 says the set stays independent) until it spans; the process cannot outrun the size of a spanning set, by Theorem 1.
Both theorems require the space to be spanned by a finite set. A vector space which cannot be spanned by any finite set is called an infinite dimensional vector space; the space P of all polynomials is one (see 6.8.3).
The step-by-step procedures above would be painfully slow, because every step re-tests the whole set. In Rm we can instead do all the deleting (or all the adding) in one row reduction.
Note
Theorem 6 (Reducing a spanning set to a basis in Rm) Suppose that S={v1,…,vn} is any subset of Rm and A is the matrix whose columns are the members of S. If U is a row-echelon form for A and S′ is created from S by deleting those vectors which correspond to non-leading columns in U, then S′ is a basis for span(S).
Take the surviving vectors from A (the original vectors), not from U — the row operations destroy the actual columns.
Example. Find a basis for, and the dimension of, the subspace of R4 spanned by
The third and fifth columns are non-leading, so we delete the third and fifth members of S and obtain the basis
S′=⎩⎨⎧1122,2345,1336⎭⎬⎫
for span(S), which is therefore 3-dimensional. Do not confuse the dimension of a subspace with the dimension of the space it lives in — span(S) is a 3-dimensional subspace of R4, and this has nothing to do with R3.
Example. Show that the vectors v1=012, v2=2−1−2, v3=324, v4=542 span R3, and find a basis for R3 which is a subset of S={v1,v2,v3,v4}.
Rather than dragging a general b through the reduction, we can find a basis for span(S) first; if its dimension turns out to be 3, then by Proposition 8 below (or Theorem 3 part 4) the span must be all of R3.
The third column is non-leading, so we delete v3; the subset B={v1,v2,v4} is a basis for span(S). But B is then a linearly independent set of 3 vectors in R3, so it is also a basis for R3 itself; in particular S spans R3.
Note
Theorem 7 (Extending a linearly independent set to a basis in Rm) Suppose that S={v1,…,vn} is a linearly independent subset of Rm and A is the matrix whose columns are the members of S followed by the standard basis vectors for Rm. If U is a row-echelon form for A and S′ is created by choosing those columns of A which correspond to leading columns in U, then S′ is a basis for Rm containing S as a subset.
The trick: the appended standard basis vectors guarantee that the columns of A span Rm, so Theorem 6 applied to this bigger set gives a basis; and because the members of S come first and are independent, their columns are all leading, so none of them get deleted.
Example. Find a basis for R4 containing the members of the linearly independent set
S=⎩⎨⎧124−2,2510−5⎭⎬⎫.
Form the matrix with the members of S followed by e1,e2,e3,e4 and reduce:
The leading columns are the first, second, fourth and fifth, so we take the corresponding columns of A and get the basis
S′=⎩⎨⎧124−2,2510−5,0100,0010⎭⎬⎫
for R4. Note that the same procedure works even when S is neither independent nor spanning — you form exactly the same matrix and keep the leading columns — but then the result may not contain all of S.
Note
Proposition 8 If V is a finite-dimensional vector space, W is a subspace of V and dim(W)=dim(V), then W=V.
Basically, a subspace cannot have full dimension without being the whole space; a basis for W is an independent set of dim(V) vectors and so, by Theorem 3 part 4, a basis for all of V.
Example. (Out of the box: dimension of a solution space) Find a basis for, and the dimension of, the solution space
S={x∈R4:Ax=0},whereA=(102001−12).
We showed in 6.3 that solution sets of homogeneous equations are subspaces; now we can measure them. The matrix is already in row-echelon form with leading columns 1 and 3, so x2=λ and x4=μ are free. Back substitution:
x3+2μx3x1+2λ−μx1=0=−2μ,=0=−2λ+μ.
Hence every solution has the form
x=λ−2100+μ10−21,
so S=span−2100,10−21. These two vectors are linearly independent (look at the second and fourth components; any combination equal to 0 forces λ=0 and μ=0), so they form a basis and dim(S)=2. In general,
dim{x:Ax=0}=number of non-leading columns of U=number of free parameters.
Example. (Out of the box: dimension of a polynomial subspace) Find a basis for, and the dimension of,
S={p∈P3(R):p(1)=0}.
Write p(x)=a0+a1x+a2x2+a3x3. The condition p(1)=0 says
Hence S=span(x−1,x2−1,x3−1). For independence, suppose λ1(x−1)+λ2(x2−1)+λ3(x3−1)=0 for all x; the coefficient of x3 gives λ3=0, the coefficient of x2 gives λ2=0, and the coefficient of x gives λ1=0. So {x−1,x2−1,x3−1} is a basis for S and dim(S)=3.
Notice the pattern; dim(P3)=4, and imposing one linear condition knocked the dimension down by exactly one. Basically, each independent linear constraint costs one dimension — the same thing happened in the solution space example (4 unknowns, 2 equations, dimension 2).
This section is marked [X] — it is MATH1241/extension material.
Any basis B for a finite-dimensional vector space V gives every vector a unique linear combination. If we also fix an order on the basis vectors, then the list of scalars in that combination becomes an unambiguous label for the vector.
Note
Definition 1
Let V be an n-dimensional vector space and let the ordered set of vectors B={v1,…,vn} be a basis for V. If
v=x1v1+⋯+xnvn,
then the vector
[v]B=x1⋮xn
is called the coordinate vector of v with respect to the ordered basis B.
Basically, once you fix an ordered basis, every vector in anyn-dimensional vector space — polynomials, matrices, functions — gets relabelled as a column vector in Fn, and then all of our matrix machinery applies to it. The order of the basis matters; shuffling the basis vectors shuffles the coordinates.
Example. With respect to the ordered basis B=⎩⎨⎧013−1,25−31,4−102,−6214⎭⎬⎫ of R4, a vector v has coordinate vector [v]B=1−342. Find v.
This direction is pure arithmetic; the coordinates are the scalars, so
Going the other way (vector to coordinates) requires solving a linear system, as in the example in 6.6.1 where we wrote b=−105 in terms of {v1,v2}; there we found b=v1−2v2, which in this language says [b]B=(1−2) with respect to the ordered basis {v1,v2} of span(v1,v2).
Example. (A non-standard polynomial basis) You are given the ordered basis B={1+x,x+x2,1+x2} for P2(R). Find the coordinate vector of p(x)=1−x2 with respect to B.
We need scalars α1,α2,α3 such that, for all x,
1−x2=α1(1+x)+α2(x+x2)+α3(1+x2).
Expanding and comparing coefficients of 1,x,x2:
α1+α3α1+α2α2+α3=1,=0,=−1.
From the second equation α2=−α1; substituting into the third,
−α1+α3=−1,
and adding this to the first equation,
2α3α3=0=0,
so α1=1 and α2=−1. Therefore [p]B=1−10. (With respect to the standard basis {1,x,x2} the coordinate vector is just the coefficients 10−1 — no working needed at all.)
Example. (Order trap in R2) Find [v]B for v=(37) with respect to the ordered basis B={(11),(1−1)}.
Setting x1(11)+x2(1−1)=(37) gives
x1+x2x1−x2=3,=7.
Adding the equations,
2x1x1=10=5,
so x2=3−5=−2 and [v]B=(5−2). With the reversed ordered basis B′={(1−1),(11)} the answer flips to (−25) — same vector, different label, so always respect the given order.
The reason coordinate vectors are safe to compute with is that they respect all the vector space operations:
Note
Theorem 1 If B is an ordered basis for a vector space V over a field F and u,v∈V and λ∈F, then a) u=v if and only if [u]B=[v]B, b) [u+v]B=[u]B+[v]B, c) [λv]B=λ[v]B.
Basically nothing is lost in translation between V and Fn; adding vectors adds their coordinate vectors, scaling scales them, and equal coordinate vectors mean equal vectors (this last part is exactly the uniqueness of linear combinations from 6.5.2). This is why a question about polynomials or matrices can always be converted into a question about columns of numbers.
This section is marked [X] — it is MATH1241/extension material, and regarded as harder than the rest of the chapter.
So far nearly all the worked examples lived in Rn. Here we apply the whole toolkit — subspaces, spans, independence, bases, dimension, coordinate vectors — to three other families: matrices, real-valued functions, and polynomials. First, a streamlined subspace test.
Note
Theorem 1 (Alternative Subspace Theorem) A subset S of a vector space V over a field F is a subspace of V if and only if S contains the zero vector and satisfies the closure condition:
if v1,v2∈S, then λ1v1+λ2v2∈S for all λ1,λ2∈F.
This is just the Subspace Theorem with the two closure checks merged into one; taking λ1=λ2=1 recovers closure under addition, and taking λ2=0 recovers closure under scalar multiplication. One line of working instead of two.
Recall from 6.1 that Mmn(R), the set of all m×n real matrices, is a vector space over R (and Mmn(C) over C).
Example. The set S={A∈M22(R):[A]11=[A]22=1} is not a subspace of M22(R); the zero matrix has 0s on its diagonal, so 0∈/S and we are done in one line.
Example. Prove that the set of n×n real symmetric matrices is a subspace of Mnn(R).
Recall that A is symmetric if A=AT. Let S be the set of n×n symmetric matrices. The zero matrix is clearly symmetric, so 0∈S. Suppose A,B∈S and λ,μ∈R. Using the properties of the transpose and the symmetry of A and B,
(λA+μB)T=λAT+μBT=λA+μB,
so λA+μB is symmetric and belongs to S. By the Alternative Subspace Theorem, S is a subspace. ■
For 1≤i≤m and 1≤j≤n, let Eij be the m×n matrix with every entry 0 except a 1 in the ijth position. Any matrix A=(aij) can be written as A=∑i∑jaijEij, and this combination is 0 only when every aij=0, so the set {Eij} is a linearly independent spanning set — the standard basis for Mmn. Counting its members confirms dim(Mmn)=mn.
Example. Show that the set {(1110),(1012),(1102),(0112)} is a basis for M22.
Since dim(M22)=4 and we have exactly 4 matrices, Theorem 3 part 4 of 6.6.2 says we only need to prove independence. Suppose
Every column is leading, so the only solution is λ1=λ2=λ3=λ4=0; the set is independent and hence a basis. Notice that the four columns of the coefficient matrix are exactly the coordinate vectors of the four matrices with respect to the standard basis {E11,E12,E21,E22} — coordinate vectors quietly converted a matrix problem into an R4 problem.
Let X be a non-empty set and let R[X]={f:X→R} be the set of all real-valued functions on X, with the usual pointwise operations
(f+g)(x)=f(x)+g(x)and(λf)(x)=λf(x)for all x∈X.
Note
Proposition 2 The system (R[X],+,∗,R) is a vector space over R.
The proof is the usual slog through the ten axioms, but nothing is deep; for instance f+g is again a real-valued function on X because f(x)+g(x) is defined and real for every x∈X, giving closure under addition, and each axiom for functions falls back onto the corresponding property of the real numbers. The zero vector is the zero function, which sends every x to 0.
Calculus is a rich source of subspaces of R[X]:
C[(a,b)], the set of continuous functions on an interval (a,b), is a subspace of R[(a,b)]; the zero function is continuous, and λ1f+λ2g is continuous whenever f and g are (a fact from calculus), so the Alternative Subspace Theorem applies.
C(1)[(a,b)], the functions with a continuous first derivative, is a subspace of R[(a,b)] by the identical argument (and it is also a subspace of C[(a,b)], since differentiable functions are continuous).
Example. Let S be the subset of R[R] defined by
S={f∈R[R]:dx2d2f−6dxdf+5f=0}.
Show that S is a subspace of R[R].
The zero function satisfies the equation, so 0∈S. For f1,f2∈S and λ1,λ2∈R, the linearity of differentiation gives
so λ1f1+λ2f2∈S, and by the Alternative Subspace Theorem S is a subspace. ■
From the theory of differential equations, the solutions of this ODE are exactly f(x)=λ1e5x+λ2ex, so S=span(e5x,ex) — a 2-dimensional space of functions. This is precisely why the "general solution" of a second order homogeneous linear ODE is written as arbitrary constants times two basis solutions; the solution set is a subspace and you are writing down a basis for it. Subspaces can also be carved out by integrals, e.g. {f∈C[−π,π]:∫−ππf(x)g(x)dx=0} for a fixed continuous g is a subspace, since integration is also linear.
Linear independence questions for functions work as in the example of 6.5.1 ({sinx,cosx} independent, {1,sin2x,cos2x} dependent). One further result is worth knowing: for every n, the set {sin(kx):k=1,…,n} is linearly independent — the slick proof multiplies ∑kλksin(kx)=0 by sin(mx), integrates from 0 to π, and uses
∫0πsin(kx)sin(mx)dx={02πk=mk=m
to force λm=0 for each m (this is an integral version of the orthonormal basis trick from 6.6.1). Since R[R] contains arbitrarily large independent sets, it cannot be spanned by any finite set; it is an infinite dimensional vector space.
Here the field F is always R or C. A polynomial over F is a function p:F→F of the form p(z)=a0+a1z+⋯+anzn with the ak∈F; addition adds corresponding coefficients and scalar multiplication multiplies each coefficient, exactly as for general functions. The key structural fact is:
Note
Proposition 3 (Uniqueness Proposition for Real and Complex Polynomials) Let p(z)=∑k=0nakzk and q(z)=∑k=0nbkzk be polynomials over F=R or C. Then p(z)=q(z) for all z∈F if and only if ak=bk for all k=0,1,…,n.
In particular p is the zero polynomial (zero for all z) if and only if every coefficient is zero. This proposition is the licence behind every "compare coefficients" step we have done; it converts an equation between polynomials into a linear system for the coefficients. (It fails over more exotic fields, but we will not meet those here.)
The set P(F) of all polynomials over F, with these operations, is a vector space over F, and Pn(F) is a subspace of it (both seen earlier). The field of scalars has to be compatible with the polynomials though:
Example. The system (P(C),+,∗,R) of complex polynomials with real scalars is a vector space, but (P(R),+,∗,C) of real polynomials with complex scalars is not; take p(x)=x∈P(R) and the scalar i∈C, then ip∈/P(R), so closure under scalar multiplication fails (all other nine axioms actually hold, which shows how a system can fail by a single axiom).
Example. Let Pn be the polynomials of degree at most n over F. Show that
S={p∈Pn:p(5)=α}
is a subspace of Pn if and only if α=0.
If α=0, the zero polynomial is not in S (it evaluates to 0=α at 5), so S is not a subspace. If α=0, the zero polynomial is in S, and for p,q∈S and λ1,λ2∈F,
(λ1p+λ2q)(5)=λ1p(5)+λ2q(5)=λ1⋅0+λ2⋅0=0,
so λ1p+λ2q∈S and, by the Alternative Subspace Theorem, S is a subspace. Therefore S is a subspace if and only if α=0; when α=0, S is the set of polynomials in Pn with a root at z=5.
Example. Does the complex polynomial p belong to span(p1,p2), where
p(z)=4+z+2z2,p1(z)=1+z−z2,p2(z)=2−z?
We need scalars x1,x2 with p=x1p1+x2p2; comparing coefficients of 1,z,z2 (using the Uniqueness Proposition),
x1+2x2x1−x2−x1=4,=1,=2.
The third equation forces x1=−2, then the second gives x2=x1−1=−3, but then
x1+2x2=−2−6=−8=4,
so the system is inconsistent and p∈/span(p1,p2).
Example. Show that the set S={2+z,−1+z2,z−z2} is a basis for P2.
Since dim(P2)=3 and S contains exactly 3 vectors, we only need to check independence (Theorem 3 part 4 again). Suppose x1(2+z)+x2(−1+z2)+x3(z−z2)=0 for all z. Collecting powers of z,
(2x1−x2)+(x1+x3)z+(x2−x3)z2=0,
so, comparing coefficients,
2x1−x2x1+x3x2−x3=0,=0,=0.
The second equation gives x3=−x1 and the first gives x2=2x1; substituting both into the third,
2x1−(−x1)3x1x1=0=0=0,
and hence x2=x3=0. The set is linearly independent, and therefore a basis for P2.
Finally, P itself has no finite basis; if a finite set S of polynomials spanned P, there would be a highest-degree polynomial in S, say of degree N, and then no polynomial of degree greater than N could ever be in span(S) (linear combinations cannot raise the degree). Hence P is infinite dimensional, while
This is a quick reference appendix; nothing here is new.
A set is any collection of elements, written with braces, e.g. S={1,4,−7}. Sets defined by a rule use set-builder notation:
S={x∈Rn:x1≥0,x3≤4}
reads "the set of vectors x in Rnsuch thatx1≥0andx3≤4" — the colon is read as "such that" and the comma as "and".
Equality.A=B means every element of A is in Band every element of B is in A; proving equality always means proving both inclusions.
Subset.A⊆B means every element of A is also an element of B.
Proper subset.A is a proper subset of B if A⊆B and at least one element of B is not in A.
Intersection.A∩B={x:x∈A and x∈B}.
Union.A∪B={x:x∈A or x∈B}.
The notation f:X→Y reads "f is a function from the set X to the set Y"; it means f assigns exactly one element f(x)∈Y to each x∈X. X is the domain and Y the codomain. Two functions f,g:X→Y are equal if and only if f(x)=g(x) for allx∈X (this "for all" is what made the polynomial and function examples in this chapter tick). The operations used throughout the chapter are all defined pointwise:
Only the first two matter for vector space structure; multiplication and composition of functions are extra operations that vector spaces know nothing about.