04. MIPS Data and Memory
Leaving the Registers#
Registers are excellent for small, temporary values, but they cannot hold an array, a string, or an entire struct. Those objects live in memory. MIPS therefore separates two jobs:
- arithmetic and comparisons operate primarily on registers;
- load and store instructions move values between memory and registers.
flowchart TD
    M["Memory at an address"] -->|lb / lh / lw| R["Register"]
    R --> C["Compute"]
    C --> R
    R -->|sb / sh / sw| M
Loading does not remove a value from memory; it copies its bits into a register. Storing copies the low part of a register into memory.
Memory Is Byte-Addressed#
MIPS memory can be imagined as a one-dimensional array of bytes. Every byte has a unique address. A multi-byte value occupies several consecutive addresses.
| C-like value | Typical size in the course MIPS environment |
|---|---|
char / byte |
1 byte |
short / half-word |
2 bytes |
int / word |
4 bytes |
| pointer | 4 bytes |
An address is itself a 32-bit value, so a pointer fits in a general-purpose register. The object pointed to normally remains in memory.
A Concrete Byte-Addressed Snapshot#
Suppose memory beginning at address 0x1000 contains these bytes:
| Address | Byte |
|---|---|
0x1000 |
78 |
0x1001 |
56 |
0x1002 |
34 |
0x1003 |
12 |
0x1004 |
FE |
0x1005 |
FF |
0x1006 |
41 |
0x1007 |
00 |
Reading from low to high addresses, the first four bytes (78 56 34 12) form one word, the next two (FE FF) form one halfword, and the final two bytes hold A and the terminating NUL byte. The instruction decides how many consecutive bytes belong to this particular access.
Every address names exactly one byte. A wider load begins at one address and consumes consecutive bytes.
To see what least significant means, split the word 0x12345678 into pairs of hexadecimal digits:
Written as separate bytes, the word is 12 | 34 | 56 | 78.
Each pair is one byte. 78 is the least significant byte because it contains the lowest-value part of the number—the rightmost eight bits. 12 is the most significant byte because it contributes the highest-value part.
Endianness answers one question: which byte receives the lowest memory address? Little-endian places the least significant byte first, giving 78 56 34 12. Big-endian places the most significant byte first, giving 12 34 56 78. The number itself has not been reversed; endianness only describes how one multi-byte value is arranged across byte addresses. Mipsy is little-endian, so the four bytes at 0x1000 form 0x12345678, not 0x78563412.
Note
- Mipsy's simplified memory layout
Mipsy places user code in a text region, global data in a data region, and function-call storage in a stack which grows towards lower addresses. Its model is intentionally friendlier than a full operating system. The official MIPS guide documents the current segment addresses and permissions.
Global and Local Values#
A global object is placed in the .data section:
	.data
counter:
	.word	0			# int counter = 0;
Small local values are often kept in registers while possible. Values whose address is needed, large objects, and values which cannot remain in registers may instead live in memory. MIPS Functions explains stack storage and register preservation.
Defining Data#
Assembler directives reserve and optionally initialise bytes:
| Directive | Effect |
|---|---|
.byte 7 |
emit one byte |
.half 7 |
emit a two-byte half-word |
.word 42 |
emit a four-byte word |
.space 16 |
reserve 16 uninitialised bytes |
.ascii "abc" |
emit three character bytes |
.asciiz "abc" |
emit the characters and a terminating zero byte |
.align 2 |
align the next object to a multiple of 4 bytes in mipsy |
Directives do not execute at runtime. They tell the assembler what bytes should exist in a section.
	.data
letter:
	.byte	'Q'
answer:
	.word	42
numbers:
	.word	1, 3, 5, 7, 9
message:
	.asciiz	"hello"
buffer:
	.space	64
Load and Store Instructions#
| Width | Signed load | Unsigned load | Store |
|---|---|---|---|
| 1 byte | lb |
lbu |
sb |
| 2 bytes | lh |
lhu |
sh |
| 4 bytes | lw |
same 32 bits | sw |
The width should match the object. Using lw for a character would read the character and three neighbouring bytes as one word, assuming the address is aligned at all.
Signed and Unsigned Loads#
A byte contains only 8 bits, but a MIPS general-purpose register contains 32. Loading one byte therefore leaves 24 new upper positions to fill. The instruction determines how they are filled.
Consider the byte 11111110, or 0xFE. The same eight bits mean 254 when interpreted as unsigned, but -2 when interpreted as a signed two's-complement value:
lbu: 00000000 00000000 00000000 11111110 = 254
lb:  11111111 11111111 11111111 11111110 = -2
lbu performs zero extension, filling every new position with zero. lb performs sign extension, copying the old leftmost bit into every new position. Copying that bit preserves the signed value as it is widened. lhu and lh make the same choice for 16-bit half-words. The two's-complement interpretation is developed fully in Integers.
	lb	$t0, 0($t2)		# load a signed int8_t-like value
	lbu	$t1, 0($t2)		# load a uint8_t-like value
Stores do not need signed and unsigned forms: sb simply writes the low eight bits, while sh writes the low sixteen. Signedness matters when the bits are interpreted after loading.
Little-Endian Load Trace#
Using the memory snapshot above and placing 0x1000 in $t0:
| Instruction | Bytes consumed | Register result | Reason |
|---|---|---|---|
lbu $t1, 0($t0) |
78 |
0x00000078 |
one byte, zero-extended |
lb $t1, 4($t0) |
FE |
0xFFFFFFFE |
signed byte 0xFE is -2 |
lhu $t1, 4($t0) |
FE FF |
0x0000FFFE |
little-endian half-word, zero-extended |
lh $t1, 4($t0) |
FE FF |
0xFFFFFFFE |
the same half-word interpreted as -2 |
lw $t1, 0($t0) |
78 56 34 12 |
0x12345678 |
four bytes assembled little-endian |
Now suppose $t2 = 0xA1B2C3D4:
	sb	$t2, 6($t0)		# writes D4 at 0x1006
	sh	$t2, 4($t0)		# writes D4 at 0x1004, C3 at 0x1005
	sw	$t2, 0($t0)		# writes D4 C3 B2 A1 from 0x1000 upward
The register itself is unchanged. A store selects its low 8, 16 or 32 bits and copies only those bits to memory.
Loading and Updating a Word#
int counter = 0;
counter++; la $t0, counter # $t0 = &counter
lw $t1, 0($t0) # $t1 = counter
addi $t1, $t1, 1 # $t1++
sw $t1, 0($t0) # counter = $t1
.data
counter:
.word 0The CPU cannot increment the memory object directly with addi. It loads, computes, then stores.
Mipsy also accepts convenient label forms:
	lw	$t1, counter
	addi	$t1, $t1, 1
	sw	$t1, counter
The explicit address-in-a-register form is usually better preparation for arrays, pointers, and structs.
Practice: Quick Checks#
- What is the difference between
la $t0, itemandlw $t0, item? - Which instructions load a signed byte, an unsigned byte, a signed half-word, an unsigned half-word and a word?
- Why are there no separate signed and unsigned forms of
sb,shandsw?
Note
- Quick Check Answers
laplaces the address&itemin$t0;lwreads the four-byte value stored atitem.lb,lbu,lh,lhuandlw, respectively.- A store merely copies the low 8, 16 or 32 bits. Signedness matters when a narrower pattern is extended during a load, not when those low bits are written.
Effective Addresses#
The common memory operand has the form:
offset(base_register)
The effective address is:
value in base_register + constant byte offset
	lw	$t0, 8($t1)		# load a word from address $t1 + 8
	sb	$t2, 3($t3)		# store one byte at address $t3 + 3
The offset is measured in bytes, even for lw. lw $t0, 4($t1) accesses the next word after the word at 0($t1).
Worked Effective-Address Trace#
If $s0 = 0x10010020, then:
lw $t0, 12($s0)is evaluated in this order:
- read the base register:
0x10010020; - add the signed constant byte offset:
12 = 0x0000000C; - obtain effective address
0x1001002C; - read four bytes beginning at that address;
- assemble those bytes into
$t0according to memory endianness.
The offset is part of the address calculation; it is not added to the value loaded from memory.
Addresses, Pointers, and Dereferencing#
Consider:
int answer = 42;
int *p = &answer;
int i = *p;
*p = 27;
In MIPS:
	la	$t0, answer		# int *p = &answer;
	lw	$t1, 0($t0)		# int i = *p;
	li	$t2, 27
	sw	$t2, 0($t0)		# *p = 27;

	.data
answer:
	.word	42
la performs address-taking; lw and sw perform dereferencing. Keep the distinction explicit:
| C | MIPS idea |
|---|---|
&answer |
la the label's address |
*p as a read |
load from 0(p_register) |
*p = value |
store to 0(p_register) |
An address is like a numbered location on a map; it is not the object found at that location. Suppose the label answer is assigned address 0x10010020, and the four bytes beginning there represent 42:
answer ---------> address 0x10010020 ---------> stored value 42
label name          where to look                 what is there
The instructions follow one arrow at a time:
	la	$t0, answer		# $t0 = 0x10010020, the location
	lw	$t1, 0($t0)		# $t1 = 42, the value found there
After la, another lw is needed because knowing where a value lives is different from reading it. Conversely, if a syscall needs a string address, loading the first four character bytes with lw would provide data rather than the required location.
Important
- Address or contents?
Assume score is stored at address 0x10010040 and contains 73. What should $t0 and $t1 contain after la $t0, score followed by lw $t1, 0($t0)? Which instruction corresponds to C's &score, and which corresponds to reading score?
Note
- Reasoned answer
$t0 contains 0x10010040, while $t1 contains 73. la corresponds to obtaining &score; lw dereferences that address and reads the stored integer. The two registers hold different kinds of value even though both are ultimately 32-bit patterns.
Alignment#
An address is aligned for a size when it begins on a boundary suitable for that kind of value. For example, addresses 0, 4, 8 and 12 are multiples of four, so they are four-byte aligned. The CPU can then fetch a four-byte word from the expected boundary instead of having it straddle two regions.
An object's required alignment is determined by its type and the platform's ABI: the agreed binary-level rules followed by the compiler, libraries and operating system. Alignment is not generally equal to an object's total size. In the course MIPS environment, a two-byte half-word is aligned to a multiple of two and a four-byte word used by lw or sw is aligned to a multiple of four. A struct normally inherits the strictest alignment required by any of its fields, which is why a 60-byte struct containing words needs four-byte alignment rather than 60-byte alignment.
This can break when a string or byte array appears before a word:
	.data
name:
	.asciiz	"hello"			# 6 bytes including terminator
count:
	.space	4			# may begin unaligned
Safer options include defining the word with .word, reordering objects, or explicitly aligning it:
	.data
name:
	.asciiz	"hello"
	.align	2			# next address is divisible by 2^2 = 4
count:
	.space	4
Hexadecimal addresses ending in 0, 4, 8, or C are divisible by four.
One-Dimensional Arrays#
An array is a sequence of equal-sized elements. If base is the address of its first element, then:
address of array[i] = base + i * sizeof(element)
Byte Array#
For char letters[], each element is one byte:
	la	$t0, letters		# base
	li	$t1, 3			# i
	add	$t2, $t0, $t1		# &letters[i]
	lb	$t3, 0($t2)		# letters[i]

	.data
letters:
	.byte	'a', 'z', 'b', 'f', 'G'
Word Array#
For int numbers[], each element occupies four bytes:
	la	$t0, numbers		# base
	li	$t1, 3			# i
	mul	$t2, $t1, 4		# byte_offset = i * sizeof(int)
	add	$t3, $t0, $t2		# &numbers[i]
	lw	$t4, 0($t3)		# numbers[i]

	.data
numbers:
	.word	16, 4, 1, 9, 2
A common mistake is using i directly as the offset for an int array. That produces an unaligned or incorrect address because MIPS offsets are bytes, not elements.
Half-Word Array#
For short samples[], each element occupies two bytes, so multiply the index by two and use lh or lhu according to the C type:
	la	$t0, samples
	li	$t1, 3			# i
	mul	$t2, $t1, 2		# byte_offset = i * sizeof(short)
	add	$t3, $t0, $t2
	lh	$t4, 0($t3)		# signed short samples[i]

	.data
	.align	1
samples:
	.half	120, -3, 900, -20
The scaling rule is now visible across the common array types:
| C element type | Bytes per element | Address of element i |
Typical load/store |
|---|---|---|---|
char / unsigned char |
1 | base + i |
lb/lbu, sb |
short / unsigned short |
2 | base + 2*i |
lh/lhu, sh |
int / unsigned int |
4 | base + 4*i |
lw, sw |
Looping Through an Array#
int sum = 0;
for (int i = 0; i < LENGTH; i++) {
	sum += numbers[i];
}LENGTH = 5
li $t0, 0 # int sum = 0;
li $t1, 0 # int i = 0;
loop_sum__cond:
bge $t1, LENGTH, loop_sum__end
mul $t2, $t1, 4 # byte_offset = i * 4;
lw $t3, numbers($t2) # int value = numbers[i];
add $t0, $t0, $t3 # sum += value;
addi $t1, $t1, 1
b loop_sum__cond
loop_sum__end:Pointer Arithmetic#
C automatically scales pointer arithmetic by the pointed-to type:
char *c = address;
c++;                 // address increases by 1

int *p = address;
p++;                 // address increases by 4
MIPS registers have no pointer type, so you perform that scaling yourself. Increment a character pointer by 1, and an integer pointer by 4.
Index-based loops are often easier to debug because the logical index and computed byte offset remain separate. Pointer loops can still be useful, particularly for strings:
	la	$t0, string		# char *p = string;
loop_string__cond:
	lb	$t1, 0($t0)		# char c = *p;
	beq	$t1, 0, loop_string__end
	# use c
	addi	$t0, $t0, 1		# p++;
	b	loop_string__cond
loop_string__end:
MIPS Strings#
A MIPS string is a byte array whose final byte is zero. The terminator is not the character '0'; it is the numeric byte 0x00. String algorithms therefore combine pointer traversal, lbu, a zero test and—when mutating—a matching sb.
Counting Characters#
This is the memory-level shape of strlen:
	la	$t0, message		# char *p = message;
	li	$t1, 0			# int length = 0;

strlen_loop:
	lbu	$t2, 0($t0)		# unsigned char c = *p;
	beq	$t2, 0, strlen_end
	addi	$t1, $t1, 1		# length++;
	addi	$t0, $t0, 1		# p++;
	b	strlen_loop

strlen_end:
	# $t1 contains 5 for "hello"

	.data
message:
	.asciiz	"hello"
The load happens before the increment. That lets the zero terminator stop the loop without being counted.
Mutating a String In Place#
The following loop converts lowercase ASCII letters to uppercase while leaving punctuation, digits and existing uppercase letters unchanged:
	la	$t0, message		# char *p = message;

uppercase_loop:
	lbu	$t1, 0($t0)
	beq	$t1, 0, uppercase_end
	blt	$t1, 'a', uppercase_next
	bgt	$t1, 'z', uppercase_next
	addi	$t1, $t1, -32		# ASCII 'a' - 'A' = 32
	sb	$t1, 0($t0)		# write the changed byte back

uppercase_next:
	addi	$t0, $t0, 1
	b	uppercase_loop

uppercase_end:
This mutation is safe only when the string resides in writable memory. The important load–compute–store pattern is the same one used for integers; only the width has changed to one byte.
Note
Checkpoint
- Memory is byte-addressed, so every load or store begins with an address.
- The instruction width (
lb,lh, orlw) must match the object being accessed. - Array indexing becomes address arithmetic: base address plus index multiplied by element size.
Practice: Writing / Translation#
- Write MIPS which loads signed
short samples[i]when$a0contains the array base and$a1containsi. - Translate
letters[i] = letters[i] + 1;for a byte array whose base is in$a0and index is in$a1. - Write a pointer loop which counts the ASCII space bytes in a zero-terminated string whose address is in
$a0. Return the count in$v0.
Note
- Writing / Translation Answers
4. Multiply i by the two-byte element size, add that byte offset to the base, then use the signed half-word load:
mul  $t0, $a1, 2
add  $t0, $a0, $t0
lh $v0, 0($t0)- A byte array needs no index scaling. Load the byte, change the register copy, then store the low byte back:
add  $t0, $a0, $a1
lbu  $t1, 0($t0)
addi $t1, $t1, 1
sb $t1, 0($t0)- Advance the pointer one byte per iteration. Stop at the zero terminator and increment the count only for a space:
li   $v0, 0
count_spaces_loop:
lbu  $t0, 0($a0)
beq  $t0, 0, count_spaces_end
bne  $t0, ' ', count_spaces_next
addi $v0, $v0, 1
count_spaces_next:
addi $a0, $a0, 1
b    count_spaces_loop
count_spaces_end:
Two-Dimensional Arrays#
C stores a normal two-dimensional array in row-major order: all of row 0, then all of row 1, and so on. Memory remains one-dimensional, so the two indices must be flattened.
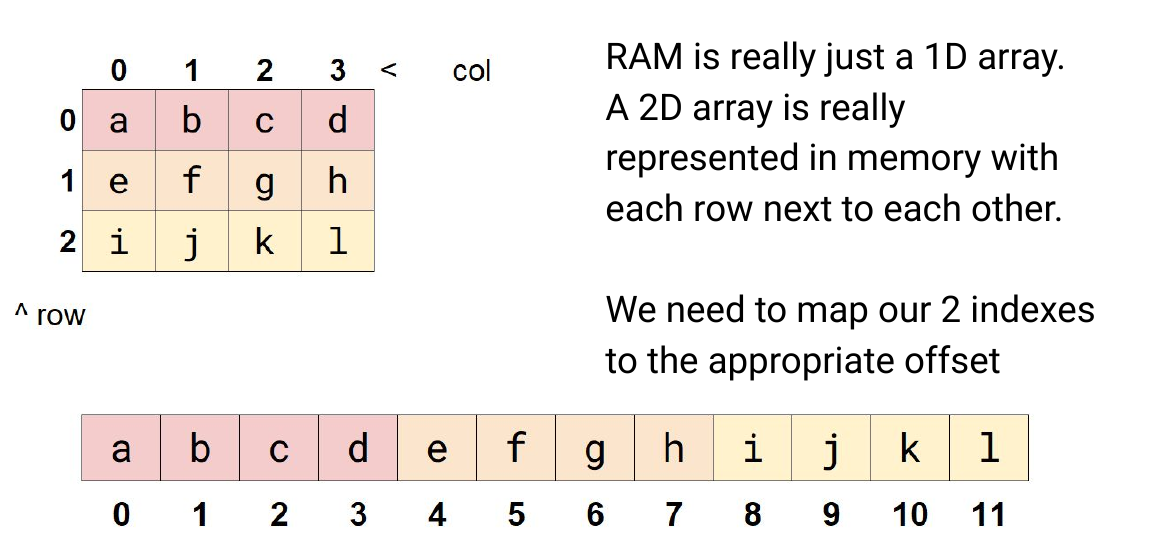
element_index = row * N_COLS + col
byte_offset   = element_index * sizeof(element)
address       = base + byte_offset
For int a[3][4], the rows occupy these flattened element indices:
| C row | Elements | Flattened indices |
|---|---|---|
a[0] |
a[0][0] through a[0][3] |
0–3 |
a[1] |
a[1][0] through a[1][3] |
4–7 |
a[2] |
a[2][0] through a[2][3] |
8–11 |
Therefore a[2][1] has element index 2 × 4 + 1 = 9. Because each int occupies four bytes, its byte offset from the array base is 9 × 4 = 36.
For int matrix[N_ROWS][N_COLS], with row in $t0 and column in $t1:
	mul	$t2, $t0, N_COLS	# row * N_COLS
	add	$t2, $t2, $t1		# row * N_COLS + col
	mul	$t2, $t2, 4		# byte offset
	lw	$t3, matrix($t2)		# matrix[row][col]
For a byte matrix, omit the final multiplication by four and use lb or sb.
Tip
Separate the formula
When debugging, inspect row * N_COLS, then the flattened element index, then the byte offset, then the final address. A single giant expression is shorter to write but harder to verify.
Structs#
A struct is a sequence of fields at known offsets from one base address. Suppose:
struct student {
	int zid;
	char first[20];
	char last[20];
	int program;
	char alias[10];
};
The fields begin at:
| Field | Offset | Size |
|---|---|---|
zid |
0 | 4 |
first |
4 | 20 |
last |
24 | 20 |
program |
44 | 4 |
alias |
48 | 10 |
The raw fields occupy 58 bytes. Because the struct contains four-byte integers, its total size is padded to a multiple of four: 60 bytes. Tail padding ensures that every element of an array of these structs also begins correctly aligned.
Seeing Internal and Tail Padding#
A smaller example makes both kinds of padding visible:
struct packet {
	char tag;
	int value;
	short code;
};| Byte offsets | Contents | Why |
|---|---|---|
| 0 | tag |
one-byte field |
| 1–3 | internal padding | align value to a multiple of four |
| 4–7 | value |
four-byte field |
| 8–9 | code |
two-byte field |
| 10–11 | tail padding | make the complete struct size a multiple of four |
On the course ABI this struct is 12 bytes, not 1 + 4 + 2 = 7. Field offsets and sizeof come from the ABI layout; do not infer them by simply adding source-level field sizes.
Define constants rather than scattering unexplained numbers:
STUDENT_ZID_OFFSET = 0
STUDENT_FIRST_OFFSET = 4
STUDENT_LAST_OFFSET = 24
STUDENT_PROGRAM_OFFSET = 44
STUDENT_ALIAS_OFFSET = 48
SIZEOF_STUDENT = 60
If $t0 contains struct student *s:
	lw	$t1, STUDENT_ZID_OFFSET($t0)	# s->zid
	lw	$t2, STUDENT_PROGRAM_OFFSET($t0)	# s->program
	addi	$t3, $t0, STUDENT_FIRST_OFFSET	# &s->first[0]
For an array students[i], first calculate i * SIZEOF_STUDENT, add the array base, then use the field offset.
address of students[i].program
= base + i * SIZEOF_STUDENT + STUDENT_PROGRAM_OFFSET
Practice: Tracing / Calculation#
- Memory from
0x2000upward contains bytes80 FF 34 12. What dolbu 0($t0),lb 0($t0),lhu 0($t0)andlh 0($t0)produce when$t0 = 0x2000on little-endian mipsy? - If
$s1 = 0x10010040, what effective address is used bylw $t2, 20($s1)? Which four addresses are read? - For
struct packet { char tag; int value; short code; };on the course ABI, give the offsets of all fields and the total size.
Note
- Tracing / Calculation Answers
7. lbu gives 0x00000080; lb gives 0xFFFFFF80; lhu combines 80 FF into 0x0000FF80; lh gives 0xFFFFFF80 because the half-word has sign bit 1.
8. The effective address is 0x10010054. lw reads addresses 0x10010054 through 0x10010057.
9. tag is at 0, bytes 1–3 are padding, value is at 4, code is at 8, bytes 10–11 are tail padding, and the total size is 12.
Combined Example: An Array of Records Containing Strings#
Consider an array whose records each contain a fixed-size string followed by a score:
struct word_record {
	char text[12];
	int score;
};
The string region occupies offsets 0–11 and the aligned integer begins at offset 12, so sizeof(struct word_record) is 16. This loop walks the record array, traverses every embedded string and accumulates both the total number of characters and the scores:
RECORD_TEXT_OFFSET = 0
RECORD_SCORE_OFFSET = 12
SIZEOF_RECORD = 16
N_RECORDS = 3

	la	$t0, records		# current struct word_record *
	li	$t1, 0			# record index
	li	$t2, 0			# total characters
	li	$t3, 0			# total score

records_loop:
	bge	$t1, N_RECORDS, records_end
	addi	$t4, $t0, RECORD_TEXT_OFFSET	# char *p = records[i].text;
	li	$t7, 12			# bytes remaining in the fixed-size text field

record_string_loop:
	beq	$t7, 0, record_string_end	# never read beyond text[12]
	lbu	$t5, 0($t4)
	beq	$t5, 0, record_string_end
	addi	$t2, $t2, 1
	addi	$t4, $t4, 1
	addi	$t7, $t7, -1
	b	record_string_loop

record_string_end:
	lw	$t6, RECORD_SCORE_OFFSET($t0)
	add	$t3, $t3, $t6
	addi	$t0, $t0, SIZEOF_RECORD	# advance one complete record
	addi	$t1, $t1, 1
	b	records_loop

records_end:
	# $t2 = 13 characters; $t3 = 11 total score

	.data
	.align	2
records:
	.asciiz	"cat"
	.space	8
	.word	2
	.asciiz	"mips"
	.space	7
	.word	5
	.asciiz	"memory"
	.space	5
	.word	4
There are two independent pointer steps: $t4 advances one byte at a time inside a string, while $t0 advances 16 bytes at a time between records. $t7 places a hard twelve-byte boundary around each string traversal, so malformed data without a terminator cannot make the loop consume the following score field. Keeping those roles in separate registers makes the nested traversal easier to verify.
Practice: Challenge#
recordsis an array of 16-bytestruct word_recordvalues, withtextat offset 0 andscoreat offset 12. Give the address formula forrecords[i].score, then explain why traversingrecords[i].textmust stop after at most 12 bytes even if the data is malformed.
Note
- Challenge Answer
The address is base + i * 16 + 12. A valid field contains a zero terminator within its 12-byte array, but malformed data may not. A bounded traversal prevents the string loop from crossing into score or the next record.
A Reliable Address Checklist#
Whenever memory code looks wrong, state these five things explicitly:
- What object am I accessing?
- What is its base address?
- What is the logical index or field?
- What byte offset does that imply?
- Which width—byte, half-word, or word—must I load or store?
If those answers are correct, the instruction is usually straightforward.