16. Unicode and UTF-8
Computers store bytes, not letters. If we want a byte sequence to represent text, we need an agreement which maps between numbers and the characters a human intends to read. That agreement is a character encoding.
Start with the euro sign printed on a screen. Several different layers are involved:
| Layer | Plain-language meaning | Example for € |
|---|---|---|
| character | the abstract textual idea, independent of any font or file format | the euro sign |
| code point | Unicode's number for that idea | U+20AC |
| encoding | rules which turn that number into stored units | UTF-8 |
| code unit | one basic storage unit used by an encoding | one byte in UTF-8 |
| encoded bytes | the actual values stored for this example | E2 82 AC |
A code point is therefore not “the bytes”, just as a house's street number is not the physical ink used to print it. The same code point can be represented using UTF-8, UTF-16 or UTF-32, producing different code units in memory or a file. Keep the fixed-width representations from Integers in mind: an encoding supplies the context which gives each bit pattern meaning.
ASCII#
ASCII is a fixed-width 7-bit encoding with 128 values, 0x00 through 0x7F. It includes:
- control characters such as NUL (
'\0') and line feed ('\n'); - punctuation;
- digits
'0'through'9'; - uppercase
'A'through'Z'; - lowercase
'a'through'z'.
The useful blocks are sequential:
int digit = c - '0';          // if c is known to be '0' ... '9'
char next = letter + 1;       // 'a' becomes 'b'
The digit trick works because the code points for the ten digits are consecutive. Do not infer that arbitrary character arithmetic is meaningful: punctuation also occupies gaps between the alphabetic blocks.
| Hex Range | Category | Key Characters / Range | Bitwise Pattern / Notes |
|---|---|---|---|
0x00 – 0x1F |
Control characters | 0x00 (NUL), 0x0A (LF / \n), 0x0D (CR / \r), 0x09 (TAB) |
Non-printable commands |
0x20 – 0x2F |
Punctuation & Space | 0x20 (Space ' '), ! " # $ % & ' ( ) * + , - . / |
First printable character is space (0x20) |
0x30 – 0x39 |
Digits ('0'–'9') |
'0' (0x30) through '9' (0x39) |
High nibble is 0x3; '5' - '0' == 5 |
0x41 – 0x5A |
Uppercase letters | 'A' (0x41 = 0100 0001₂) through 'Z' (0x5A) |
Bit 5 is 0 |
0x61 – 0x7A |
Lowercase letters | 'a' (0x61 = 0110 0001₂) through 'z' (0x7A) |
Bit 5 is 1 (differs from uppercase by 0x20) |
0x7F |
Control character | DEL (Delete) |
0111 1111₂ (all 7 bits set) |
Tip
Notice that uppercase 'A' (0x41 = 01000001₂) and lowercase 'a' (0x61 = 01100001₂) differ only at bit 5 (1 << 5 = 0x20). Toggling bit 5 with XOR (c ^ 0x20) flips the case of an ASCII alphabetic character.
Unicode#
Unicode provides a common coded character set for writing systems, symbols and control characters. Its codespace is simply the full range of numbers reserved for possible code points: U+0000 through U+10FFFF, giving 1,114,112 positions. Not every position is assigned to a character.
A Unicode scalar value is a code point which an encoding such as UTF-8 is allowed to represent: any value in that codespace except U+D800 through U+DFFF. That excluded surrogate range exists for UTF-16's internal design; it is not a set of standalone characters.
Code points are conventionally written as U+ followed by at least four hexadecimal digits:
| Character | Code point |
|---|---|
A |
U+0041 |
€ |
U+20AC |
字 |
U+5B57 |
😀 |
U+1F600 |
Unicode is not merely “one giant font”. It standardises character identities and properties. A glyph is the visible shape eventually drawn by a particular font and rendering system. One character can have different glyphs in different fonts, and one displayed glyph can sometimes depend on several code points.
Note
- Characters are more complicated than code points
A user-perceived character can contain multiple code points. For example, é may be one precomposed code point, or an e followed by a combining acute-accent code point. Emoji can join several code points into one displayed symbol. A grapheme cluster is the group a user would usually treat as one character when moving the cursor or pressing Backspace. COMP1521 mainly asks you to count and decode UTF-8 code points, but real text editors need this higher-level unit too.
UTF-32#
UTF-32 uses a 32-bit code unit for each Unicode scalar value. Conceptually, the value stored is the code point:
A   U+0041   -> 00000041
€   U+20AC   -> 000020AC
字  U+5B57   -> 00005B57
😀  U+1F600  -> 0001F600
The fixed width makes indexing by code point simple, but wastes space for ASCII-heavy text. It also still does not guarantee that one code unit equals one user-perceived character.
UTF-8#
UTF-8 is a variable-width encoding which represents one Unicode scalar value using one to four bytes:
| Bytes | Payload bits | Pattern |
|---|---|---|
| 1 | 7 | 0xxxxxxx |
| 2 | 11 | 110xxxxx 10xxxxxx |
| 3 | 16 | 1110xxxx 10xxxxxx 10xxxxxx |
| 4 | 21 | 11110xxx 10xxxxxx 10xxxxxx 10xxxxxx |
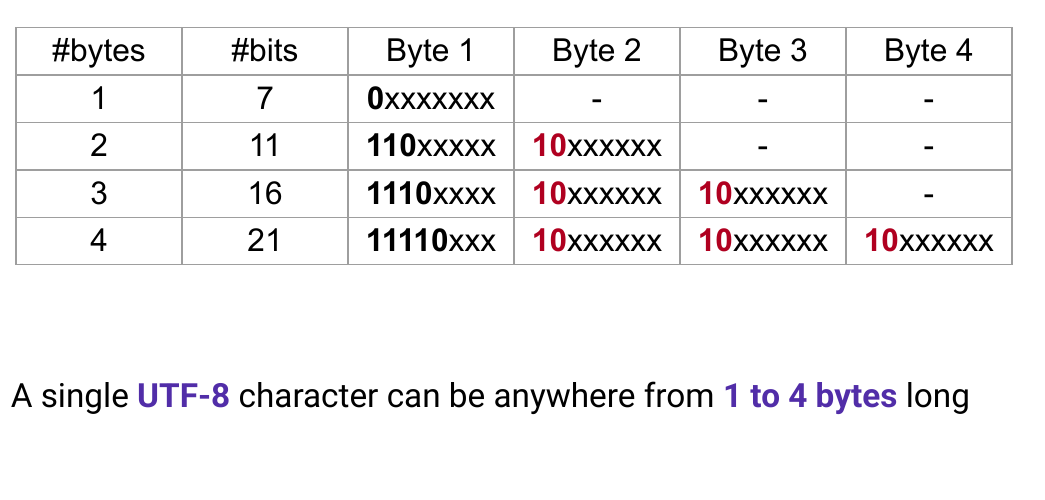
The x bits carry the code point; the fixed 0, 10, 110, 1110 and 11110 bits describe the structure. A continuation byte reserves its first two bits as 10, leaving six of its eight bits available for code-point data. Prefixes make the structure self-identifying:
0xxxxxxxis an ASCII byte and a complete one-byte character;110xxxxx,1110xxxxand11110xxxbegin two-, three- and four-byte sequences;10xxxxxxis a continuation byte.
Use the leading-byte table and image above as a decision procedure: 0xxxxxxx means one byte total, 110xxxxx means two, 1110xxxx means three, and 11110xxx means four. A byte beginning 10 is a continuation byte, so it cannot begin a new character by itself.
ASCII is therefore a byte-for-byte subset of UTF-8. Bytes 0x00 through 0x7F never appear inside the multibyte encoding of another code point. In particular, a continuation byte cannot be zero or /, which lets UTF-8 fit safely into the existing Unix conventions for NUL-terminated pathnames.
Practice: Quick Checks#
- Distinguish a character, a code point, a Unicode scalar value and a UTF-8 byte sequence.
- What prefix identifies a continuation byte, and which masks can test its two high bits?
Note
- Quick Check Answers
- A character is an abstract textual element; a code point is a numbered position in the Unicode codespace; a scalar value excludes surrogate code points; UTF-8 is a variable-width byte encoding of those scalar values. A user-perceived grapheme may contain several code points.
- A continuation byte has prefix
10xxxxxx. Test(byte & 0xC0) == 0x80.
Encoding a Code Point#
Take €, code point U+20AC:
- Write the value in binary:
10 000010 101100. - Split it from the right into six-bit groups.
- It needs three groups, so choose the three-byte template.
- Insert the payload bits and zero-fill unused leading payload positions.
template: 1110xxxx 10xxxxxx 10xxxxxx
payload:         10   000010   101100
result:   11100010 10000010 10101100
hex:         E2       82       AC
More examples:
| Character | Code point | UTF-8 bytes |
|---|---|---|
A |
U+0041 |
41 |
€ |
U+20AC |
E2 82 AC |
字 |
U+5B57 |
E5 AD 97 |
😀 |
U+1F600 |
F0 9F 98 80 |
Decoding UTF-8#
To recover the code point:
- determine the length from the leading-byte prefix;
- verify that the required following bytes begin with
10; - remove all structural prefix bits;
- concatenate the payload bits.
For E2 82 AC:
11100010 10000010 10101100
    0010   000010   101100
       10 000010 101100
       0x20AC
Validating real UTF-8 requires more than checking prefixes. A decoder must reject:
- truncated sequences;
- a continuation byte where a leading byte is expected;
- a non-continuation byte inside a multibyte sequence;
- overlong encodings, where a value uses more bytes than necessary;
- surrogate code points
U+D800throughU+DFFF; - values above
U+10FFFF.
Warning
- A common exam shortcut
If a question only asks how many structurally indicated UTF-8 characters occur, prefix patterns may be sufficient. If it asks whether the sequence is valid UTF-8, check the entire sequence and the decoded value.
Practice: Encoding, Decoding and Validation#
- Decode
F0 9F 98 80by removing the structural prefix bits and concatenating the payload. Which scalar value is it? - Explain why each sequence is invalid UTF-8:
E2 82,C0 AF,ED A0 80, andF4 90 80 80.
Note
- Encoding, Decoding and Validation Answers
3. The payload bits form hexadecimal 1F600, so the scalar value is U+1F600 (😀).
4. E2 82 is truncated; C0 AF is an overlong encoding; ED A0 80 decodes into the surrogate range; F4 90 80 80 represents a value above U+10FFFF.
Working with UTF-8 in C#
A C string is still a zero-terminated array of char. The library sees bytes; it does not automatically see Unicode code points.
char message[] = "A€字😀";
printf("%zu bytes\n", strlen(message));
In UTF-8 this contains 1 + 3 + 3 + 4 = 11 bytes before the terminating zero. strlen(message) therefore returns 11, not 4.
If the input is already known to be well-formed UTF-8, a simple code-point count can count bytes which are not continuation bytes:
#include <stddef.h>

size_t utf8_code_points(const unsigned char *s) {
	size_t count = 0;

	for (size_t i = 0; s[i] != '\0'; i++) {
		if ((s[i] & 0xC0) != 0x80) {
			count++;
		}
	}

	return count;
}
0xC0 is 11000000. Masking with it preserves the first two bits. Continuation bytes have the pattern 10xxxxxx, so they produce 0x80 and are not counted. Bitwise Operations develops the mask-and-compare technique in detail.
This is not a validator. Invalid leading bytes would also be counted. A safer routine validates and advances according to the leading byte:
int utf8_sequence_length(unsigned char byte) {
	if ((byte & 0x80) == 0x00) return 1; // 0xxxxxxx
	if ((byte & 0xE0) == 0xC0) return 2; // 110xxxxx
	if ((byte & 0xF0) == 0xE0) return 3; // 1110xxxx
	if ((byte & 0xF8) == 0xF0) return 4; // 11110xxx
	return -1;
}
The full decoder must then check each continuation byte and reject illegal values.
UTF-8 Across Read Boundaries#
A file or pipe returns chunks of bytes, not whole Unicode characters. A valid multibyte sequence can therefore be split between two successful reads:
Suppose the stream is 41 E2 82 AC 0A, which encodes A, €, then a newline. A first read might return only 41 E2 82; the second then returns AC 0A.
After the first read, 41 is a complete ASCII code point, but E2 82 is only the beginning of the three-byte encoding E2 82 AC. It is not invalid merely because the current buffer ended. A streaming decoder retains that incomplete prefix and completes it when the next chunk arrives. It reports truncation only if the overall input ends before the required continuation bytes arrive.
| Chunk | Safe action |
|---|---|
41 E2 82 |
decode 41 as U+0041 (A); retain the incomplete E2 82 prefix |
append AC 0A |
decode E2 82 AC as U+20AC (€), then decode 0A as U+000A (newline) |
This separates two different events: end of the current buffer means “obtain more bytes”, while end of the entire input means an unfinished sequence is truly truncated.
Important
- Chunked decoding
A pipe first returns F0 9F and later returns 98 80 21. What should a streaming UTF-8 decoder do after each read?
Note
- Reasoned answer
After the first read it recognises the start of a four-byte sequence but has only two bytes, so it retains F0 9F without accepting or rejecting a code point yet. It prepends those bytes to the next chunk, validates F0 9F 98 80 as U+1F600, then decodes 21 as ASCII !. If EOF arrived before 98 80, the retained prefix would be a truncated sequence.
Practice: Writing and Debugging#
- The simple
utf8_sequence_length()helper accepts leading byte0xC0as a two-byte start. Why is that insufficient validation, and what later check is required? - A loop counts every byte for which
(byte & 0xC0) != 0x80. Give one kind of malformed input it would still count as a code-point start.
Note
- Writing and Debugging Answers
5. Prefix shape alone accepts illegal starts such as C0 and C1, which can only form overlong encodings. A full decoder must assemble the value and reject overlong forms, surrogates, out-of-range values, bad continuations and truncation.
6. An invalid leading byte such as 0xFF, or an isolated legal-looking start followed by missing/invalid continuation bytes, is still counted.
Bytes, Code Points and Display Width#
These counts answer different questions:
| Question | Relevant unit |
|---|---|
| How much memory does this UTF-8 string occupy? | bytes |
| How many encoded Unicode scalar values are present? | code points |
| How many characters does a user perceive? | grapheme clusters |
| How many terminal columns will it occupy? | display width |
For plain ASCII, all four often coincide. Unicode makes the distinction visible.
Practice: Challenge#
- The UTF-8 string
A€😀is followed by a terminating zero. What dostrlen()and a valid code-point counter return, and how many bytes of array storage are occupied including the terminator? - Why can neither the UTF-8 byte count nor the code-point count reliably predict terminal columns?
Note
- Challenge Answers
7. The payload uses 1 + 3 + 4 = 8 bytes, so strlen() returns 8; the code-point count is 3; the array occupies 9 bytes including \0.
8. Grapheme clusters may combine several code points, while glyphs can occupy zero, one, two or context-dependent display columns. Display width belongs to a higher rendering layer.
Note
- Further reading
The course's official Unicode topic notes include the historical path from telegraphs to variable-width encodings. The Unicode Consortium's technical introduction gives the larger model, while the current standard's encoding-forms chapter defines UTF-8, UTF-16 and UTF-32 precisely.